Home Blog Page 1183

Thunder Bird – A Western themed action shooter by Eleanor Burns for the C64

Thunder Bird – A Western themed action shooter by Eleanor Burns for the C64


When it comes to games developed using the SEUCK engine, they are usually Shoot ’em ups that vary in quality, with some feeling a bit boring and rather samey. Thankfully ‘Thunder Bird’ by Eleanor Burns is an exception. As not only is it a Western themed action six shooter platformer, but you’ll have fun blasting different enemies with gun in hand such as snakes and nasty miners. To coincide with this news, we’ve got the full details and gameplay footage below.

And here’s the latest from the TND competition page. “Yeehaw. It is time to take a trip down to the Wild West with a Western themed action six shooter platformer by Eleanor Burns with some nice western themed music by Richard/TND. The game was created using Martin Piper’s adaptation of the Sideways Scrolling SEUCK. You play the role of an outlaw named Zintkala from the Lakota Tribe, who is on a quest for vengeance to find and defeat an evil Demon Serpent that killed her tribe leader. Before she can get there for the ultimate showdown, she must go on a long journey by foot and then by train where she will encounter broken ledges, deadly snakes, buffalo, voodoo skulls and nasty miners who made her life a real misery. Luckily she is armed with a Colt with plenty of bullets and is ready to take on the goddarn varmits. Yeehaw!”.

Links :1) Source 2) Game


Source link

Broadcast Infrastructure Market 2025-2032: Industry Outlook, Trends Analysis, New Opportunities, and Prospects | Cisco Systems, Inc., Clyde Broadcast Technology | Web3Wire

0
Broadcast Infrastructure Market 2025-2032: Industry Outlook, Trends Analysis, New Opportunities, and Prospects | Cisco Systems, Inc., Clyde Broadcast Technology | Web3Wire


Broadcast Infrastructure Market

The latest research study released by Coherent Market Insights on “Broadcast Infrastructure Market 2025 Forecast to 2032” research provides accurate economic, global, and country-level predictions and analyses. It provides a comprehensive perspective of the competitive market as well as an in-depth supply chain analysis to assist businesses in identifying major changes in industry practices. The market report also examines the current state of the Broadcast Infrastructure industry, as well as predicted future growth, technological advancements, investment prospects, market economics, and financial data. This study does a thorough examination of the market and offers insights based on an industry SWOT analysis. The report on the Broadcast Infrastructure Market provides access to critical information such as market growth drivers, market growth restraints, current market trends, the market’s economic and financial structure, and other key market details.

Get an Exclusive Sample Copy of the Report at: https://www.coherentmarketinsights.com/insight/request-sample/4555

Furthermore, The report provides a detailed understanding of the market segments which have been formed by combining different prospects such as types, applications, and regions. Apart from this, the key driving factors, restraints, potential growth opportunities, and market challenges are also discussed in the report.

The updated Version Report & online dashboard will help you understand:

Competitive LandscapeHistorical data & forecastsCompany revenue sharesRegional assessmentLatest trends & dynamics

Major Key Players:

Cisco Systems, Inc., Clyde Broadcast Technology, CS Computer Systems Ltd., Dacast Inc., EVS Broadcast Equipment SA, Grass Valley, Kaltura, Nevion, Ross Video Ltd, and Zixi.

Detailed Segmentation:

On the basis of Component type, the global broadcast infrastructure market is segmented into:

HardwareSoftwareServicesPersonal ServicesManaged ServicesOn the basis of Technology type, the global broadcast infrastructure market is segmented into:

Digital BroadcastingAnalog BroadcastingOn the basis of Application type, the global broadcast infrastructure market is segmented into:

OTTTerrestrialSatelliteIPTVOthers

Report Drivers & Trends Analysis:

The report also discusses the factors driving and restraining market growth, as well as their specific impact on demand over the forecast period. Also highlighted in this report are growth factors, developments, trends, challenges, limitations, and growth opportunities. This section highlights emerging Broadcast Infrastructure Market trends and changing dynamics. Furthermore, the study provides a forward-looking perspective on various factors that are expected to boost the market’s overall growth.

Competitive Landscape Analysis:

In any market research analysis, the main field is competition. This section of the report provides a competitive scenario and portfolio of the Broadcast Infrastructure Market’s key players. Major and emerging market players are closely examined in terms of market share, gross margin, product portfolio, production, revenue, sales growth, and other significant factors. Furthermore, this information will assist players in studying critical strategies employed by market leaders in order to plan counterstrategies to gain a competitive advantage in the market.

The global Broadcast Infrastructure market, based on different geographic regions, is divided as follows:

➤ North America (the United States, Canada, and Mexico)➤ Europe (Germany, France, UK, Russia, and Italy)➤ Asia-Pacific (China, Japan, Korea, India, and Southeast Asia)➤ South America (Brazil, Argentina, Colombia, etc.)➤ The Middle East and Africa (Saudi Arabia, UAE, Egypt, Nigeria, and South Africa)

Book the Latest Edition of this Market Study Get Up to 25% Discount At: https://www.coherentmarketinsights.com/insight/buy-now/4555

Key Features of the Broadcast Infrastructure Market Report:

✅ Analyze competitive developments such as expansions, deployments, new product launches, and market acquisitions.

✅ Examine the market opportunities for stakeholders by identifying higher growth sections.

✅ To study and analyze the global Broadcast Infrastructure industry status and forecast including key regions.

✅ An in-depth analysis of key product segments and application spectrum, providing strategic recommendations to incumbents and new entrants to give them a competitive advantage over others.

✅ It provides a comprehensive analysis of key regions of the industry as well as a SWOT analysis and Porter’s Five Forces analysis to provide a deeper understanding of the market.

✅ It helps you make strategic business decisions and investment plans.

Here we have mentioned some vital reasons to purchase this report:

➤ Regional report analysis highlighting the consumption of products/services in a region also shows the factors that influence the market in each region.

➤ Reports provide opportunities and threats faced by suppliers in the Broadcast Infrastructure and tubes industry around the world.

➤ The report shows regions and sectors with the fastest growth potential.

➤ A competitive environment that includes market rankings of major companies, along with new product launches, partnerships, business expansions, and acquisitions.

➤ The report provides an extensive corporate profile consisting of company overviews, company insights, product benchmarks, and SWOT analysis for key market participants.

➤ This report provides the industry’s current and future market outlook on the recent development, growth opportunities, drivers, challenges, and two regional constraints emerging in advanced regions.

Book the Latest Edition of this Market Study Get Up to 25% Discount At: https://www.coherentmarketinsights.com/insight/buy-now/4555

Why Choose This Broadcast Infrastructure Market Report:

Gain a reliable outlook of the global Broadcast Infrastructure market forecasts from 2025 to 2032 across scenarios.Identify growth segments for investment.Stay ahead of competitors through company profiles and market data.

[FAQ]:

What is the scope of this report?Does this report estimate the current market size?Does the report provides market size in terms of – Value (US$ Mn) and Volume (thousand ton/metric ton/cubic meter) – of the market?Which segments are covered in this report?What are the key factors covered in this report?Does this report offer customization?

The report concludes with a summary of the key findings, implications for stakeholders in the Broadcast Infrastructure Market, and recommendations for future actions based on the report’s analysis.

Overall, the Broadcast Infrastructure Market research report is a valuable tool for businesses and investors seeking to gain a deeper understanding of the Broadcast Infrastructure Market and make informed decisions based on the analysis provided.

Author of this marketing PR:

Alice Mutum is a seasoned senior content editor at Coherent Market Insights, leveraging extensive expertise gained from her previous role as a content writer. With seven years in content development, Alice masterfully employs SEO best practices and cutting-edge digital marketing strategies to craft high-ranking, impactful content. As an editor, she meticulously ensures flawless grammar and punctuation, precise data accuracy, and perfect alignment with audience needs in every research report. Alice’s dedication to excellence and her strategic approach to content make her an invaluable asset in the world of market insights.

533 Airport Boulevard,Suite 400, Burlingame,CA 94010, United StatesPhone: US +12524771362UK +442039578553AUS: +61-2-4786-0457INDIA: +91-848-285-0837Email: sales@coherentmarketinsights.com

About Us:

Coherent Market Insights is a global market intelligence and consulting organization that provides syndicated research reports, customized research reports, and consulting services. We are known for our actionable insights and authentic reports in various domains including aerospace and defence, agriculture, food and beverages, automotive, chemicals and materials, and virtually all domains and an exhaustive list of sub-domains under the sun. We create value for clients through our highly reliable and accurate reports. We are also committed in playing a leading role in offering insights in various sectors post-COVID-19 and continue to deliver measurable, sustainable results for our clients.

This release was published on openPR.

About Web3Wire Web3Wire – Information, news, press releases, events and research articles about Web3, Metaverse, Blockchain, Artificial Intelligence, Cryptocurrencies, Decentralized Finance, NFTs and Gaming. Visit Web3Wire for Web3 News and Events, Block3Wire for the latest Blockchain news and Meta3Wire to stay updated with Metaverse News.


Source link

Binance Introduces Babylon (BABY) on HODLer Airdrops Program

0
Binance Introduces Babylon (BABY) on HODLer Airdrops Program


Binance will list BABY with a seed tag on HODLer Airdrops before listing it for spot trading.

binance-logo-2

Listing Details

Users have to lock BNB on Binance Simple Earn in a period from 2025-03-07 00:00 (UTC) to 2025-03-12 23:59 (UTC) for BABY airdrop allocation.

BABY Spots listing date: 2025-04-10 10:00 (UTC).Trading pairs available: USDT, USDC, FDUSD, BNB, and TRY.Airdrops Rewards: 75,000,000 BABY (0.75% Total Supply).

BABY Token Details

Token: Babylon (BABY)

Total Supply: 10,000,000,000 BABY 

Max Supply: Infinite

Circulating Supply: 2,294,036,491 BABY (22.90% of total supply)

binance-logo-2binance-logo-2
BABY Token DetailsBABY Token Details

BABY token allocation – Source: Cryptorank

About Babylon

Babylon (BABY) is both a blockchain project and its associated token, BABY. As part of the innovative Babylon Genesis network, it aims to bolster the security of Proof-of-Stake (PoS) blockchains by harnessing the robust security framework of Bitcoin. Essentially, Babylon is building a Bitcoin Secured Network (BSN) that connects Bitcoin’s Proof-of-Work (PoW) security with the adaptability of PoS chains. This allows Bitcoin holders to stake their BTC to secure other networks and earn rewards, unlocking the potential of their idle Bitcoin without needing to sell or move it from the Bitcoin blockchain.

The project employs a dual-staking system where both Bitcoin (BTC) and the BABY token can be staked to secure the Babylon Genesis network and participating PoS chains. This “Bitcoin Staking” process involves a time-lock mechanism for BTC, while BABY serves as the network’s operational and governance token.

Ultimately, Babylon strives to create a decentralized ecosystem where Bitcoin stakers, BABY holders, and validators work together to ensure network integrity and earn rewards, effectively bridging the security of Bitcoin with the flexibility of PoS systems.


Source link

Solana Introduces Confidential Balances To Enhance Confidentiality In Its Ecosystem

Solana Introduces Confidential Balances To Enhance Confidentiality In Its Ecosystem


In Brief

Solana has launched Confidential Balances on mainnet, introducing the first encrypted token standard to meet institutional compliance requirements while ensuring near-instant transaction finality.

Solana Introduces Confidential Balances To Enhance Confidentiality In Its Ecosystem

Developers behind the Solana blockchain platform have announced the launch of Confidential Balances token extensions on the Solana mainnet. Confidential Balances introduce the first encrypted token standard, powered by zero-knowledge (ZK) technology, designed to meet institutional compliance requirements while maintaining near-instant transaction finality.

The feature encompasses several cryptographically enhanced token extensions, such as:  confidential transfers, which use cryptographic methods to obscure transfer amounts.  

Additionally, it includes a confidential transfer fee, which applies the same cryptographic techniques to ensure the confidentiality of transaction fees.  Meanwhile, confidential mint and burn allow token issuers to conceal the amounts of tokens minted or burned, in addition to obscuring the token amounts in transit.  

This system offers a flexible, on-chain mechanism for managing token amounts discreetly, including handling fee deductions, minting, burning, and auditing processes. Solana-based projects can now configure these confidentiality features to suit their specific needs, enabling decentralized applications (dApps) to provide a balanced approach to confidentiality while staying compliant with regulatory standards.

Confidential Balances: Implementation Today And Future Outlook

Developers on the Solana blockchain have already created reference implementations using pure Rust to manage the confidential token flows, with server-side solutions handling user instructions, generating ZK-proofs, and managing encryption keys. Although user-facing wallets are still in the process of fully supporting these features, the “Wallets-as-a-Service” model, where third-party services handle the heavy lifting of cryptography, is expected to accelerate adoption among everyday users. 

The next anticipated milestone is the arrival of JavaScript-based ZK-proof libraries, expected later in 2025. Once these libraries are available, developers will be able to build user-friendly wallet integrations for browsers and mobile devices that generate and validate ZK-proofs on the fly. This will make it possible for users to generate proofs directly within their web or mobile wallets without needing external servers or special instructions. 

In addition, cryptocurrency wallets like Phantom or Backpack may integrate support for confidential balances, allowing users to send tokens discreetly and easily. Furthermore, with the optional “Auditor Key” feature, these solutions will also help address institutional and regulatory concerns, ensuring that confidential tokens can be monitored within established compliance frameworks. With these upcoming features, Solana is well-positioned to offer discreet token capabilities that balance both user demands and regulatory expectations.

Disclaimer

In line with the Trust Project guidelines, please note that the information provided on this page is not intended to be and should not be interpreted as legal, tax, investment, financial, or any other form of advice. It is important to only invest what you can afford to lose and to seek independent financial advice if you have any doubts. For further information, we suggest referring to the terms and conditions as well as the help and support pages provided by the issuer or advertiser. MetaversePost is committed to accurate, unbiased reporting, but market conditions are subject to change without notice.

About The Author


Alisa, a dedicated journalist at the MPost, specializes in cryptocurrency, zero-knowledge proofs, investments, and the expansive realm of Web3. With a keen eye for emerging trends and technologies, she delivers comprehensive coverage to inform and engage readers in the ever-evolving landscape of digital finance.

More articles


Alisa Davidson


Alisa, a dedicated journalist at the MPost, specializes in cryptocurrency, zero-knowledge proofs, investments, and the expansive realm of Web3. With a keen eye for emerging trends and technologies, she delivers comprehensive coverage to inform and engage readers in the ever-evolving landscape of digital finance.


More articles


Source link

What time does Marvel Rivals season 2 release in your time zone?

What time does Marvel Rivals season 2 release in your time zone?


Season 2, the second major content update for Marvel Rivals, is based on the Hellfire Gala, a red carpet event from the X-Men series.

Season 2 will add two new characters to the game: Emma Frost, a vanguard, and Ultron, whose class type hasn’t been revealed yet. There’s also the new Krakoa map. As with season 1, season 2 will be split into two halves. Emma Frost and the Krakoa map will come with the launch and Ultron coming in the mid-season patch.

In this Marvel Rivals guide, we’ll cover when season 2 releases in your time zone and what you can expect from the season.

Marvel Rivals season 2 release time on PC, PS5, and Xbox

The first half of Marvel Rivals season 2 will launch at 4 a.m. EDT on Friday, April 11. Here’s when that is in your time zone:

The launch of season 2 will be global across PlayStation 5, Windows PC, and Xbox Series X. NetEase Games has yet to reveal the official date for the second half of season 2, but it’s expected to last for about six weeks, so until late May or early June 2025.

What to expect from Marvel Rivals season 2

The big feature in the first half of season 2 is Emma Frost, the new vanguard character. She’s able to use her psychic powers and diamond skin to project shields, mitigate damage, choke-slam enemies, and force foes to walk toward her against their will.

There is also the new Hellfire Gala map, which takes place on the island of Krakoa, adding a new region type to the game. With the addition of Hellfire Gala, NetEase games will be rotating some older maps out of the competitive playlist. All maps will still be playable in-game, just not while on the ranked grind.

Speaking of ranked, the second season will come with another reset for players, and will also see the introduction of the pick/ban phase for players in the gold rank.

NetEase Games has also implement a balance pass on the over-performing and underperforming heroes from season 1. This comes alongside an evolution of the Team-Up system, where some characters will lose their Team-Up abilities in favor of new ones.

For more Marvel Rivals guides, here’s a list of all known codes and a look at the game’s roadmap.


Source link

Michael Malone Tattoo Artist Down to Cover Up Nuggets Championship Ink

    0
    Michael Malone Tattoo Artist Down to Cover Up Nuggets Championship Ink


    Michael Malone
    Tattoo Regrets After Nuggets Firing???
    Artist Offers Cover-Up!!!

    Published April 9, 2025 12:30 AM PDT

    If Michael Malone is having regrets over his Nuggets tattoo now that the team unceremoniously fired him, the man who put the ink on the coach’s body tells TMZ Sports he’s down to cover it up.

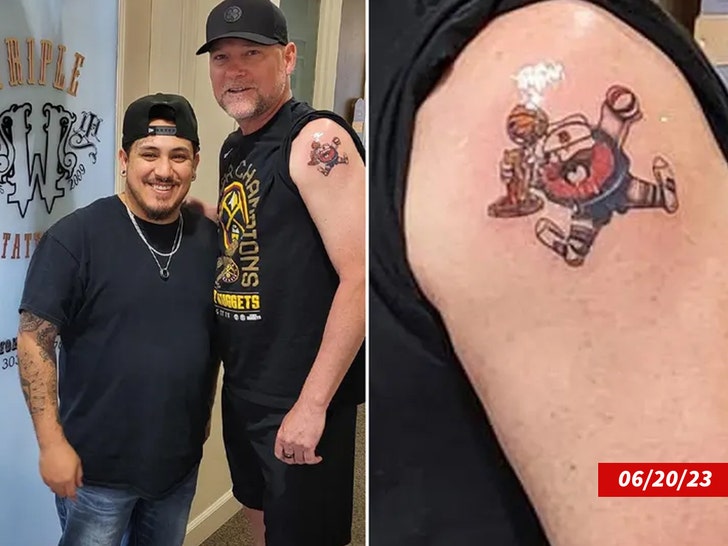
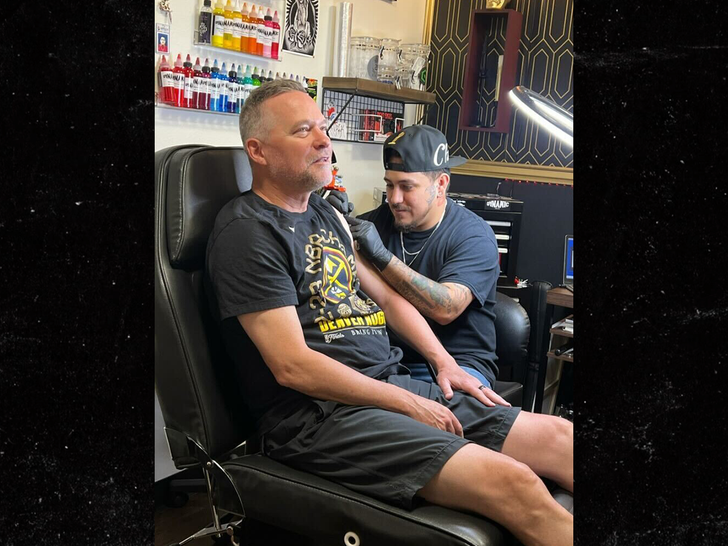
    The former Denver head man famously got the Maxie the Miner piece etched onto his shoulder after he won his first-ever NBA title two years ago … but if he now wants it gone, Mike Diaz of Triple W Tattoos says he’ll break out his needle once more.

    Michael Malone nuggets tattoo

    The artist — who designed the whimsical championship piece for Malone in June 2023 — told us he’s hopeful the 53-year-old will keep it, as it’s an amazing memory for him and his city … but he added, “If he really wanted to do that, I would help out.”

    So far, there’s been no indication Malone is looking to part ways with the artwork — Diaz said he’s yet to be contacted by anyone in the coach’s camp — but given the way Malone lost his job this week, it seems like a possibility.

    Michael Malone tattoo artist Mike Diaz

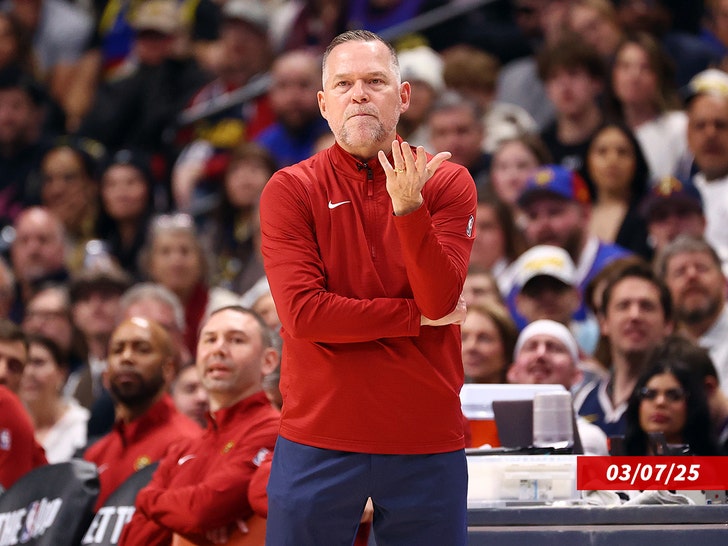
    As we reported, the Nugs fired their sideline manager after 10 years on the job … less than two weeks before the start of the playoffs.

    Menendez Brothers Prison Interview INLINE-hulu

    While Denver had been scuffling as of late, it still had a 47-32 record and had a legitimate shot at locking up the three seed.

    michael-malone-nuggets-sideline-getty-1

    If Malone ultimately decides to ditch it, the tat could still be part of other Nuggets fans’ collections … as Diaz tells us he’ll recreate the piece for a special $52.80 — the same deal he offered back when the Nuggets won it all in 2023.


    Source link

    Bitcoin, Ethereum Dip as Trump’s Tariffs on China Take Effect – Decrypt

    0
    Bitcoin, Ethereum Dip as Trump’s Tariffs on China Take Effect – Decrypt


    The fallout from this month’s trade policy from the White House continues to hound global markets, including crypto.

    Bitcoin has dipped 4.1% to $76,550, while Ethereum is down 8.3% over the last 24 hours as President Donald Trump’s tariffs on Chinese goods took effect past midnight Tuesday.

    Ethereum has witnessed the steepest decline on the day among the top 10 largest tokens, trading at its lowest point since March 2023.

    It comes as Bitcoin briefly fell below the $75,000 level late Tuesday, less than three hours before the tariffs took effect. Bitcoin is down roughly 30% since its January peak above $109,000, right before Trump’s inauguration.

    Major altcoins also posted losses. Dogecoin is down 16.3% on the day, while Solana and Cardano are down 18% and 23.7% over the past week, CoinGecko data shows.


    “It’s been a miserable run for investors since the start of February, with more than $1.2 trillion in value wiped from the crypto market,” Pav Hundal, lead market analyst at Swyftx, told Decrypt. “The markets need a circuit breaker on sentiment as much as anything else.” 

    Liquidation data from CoinGlass shows significant market distress, with the total running to roughly $411 million over the last 24 hours.

    “This has been a very emotional journey,” Hundal said. “Everyone’s operating at extremes and there’s no in-between.”

    Mounting tariff turmoil

    The crypto market’s selloff mirrors broader financial market turmoil as Trump’s tariff blitz over the past week has intensified the “trade war” between the world’s two largest economies.

    Asian markets opened sharply lower on Wednesday, with Japan’s Nikkei 225 falling 2.6% by the midday break, and Australia’s ASX 200 losing 2%.It follows a 1.5% decline in the S&P 500 on Tuesday, bringing its losses since mid-February to nearly 20%, where it is now approaching bear market territory.

    “We’ve entered a new era of protectionism, and what’s worrying is we still have no more clarity on where it’s all going to settle,” Hundal argued.  “All eyes now will be on how quickly the U.S. can barter new trade and non-trade deals.”

    The market turbulence coincides with key movements in bond and yield markets.

    The 10-year Treasury yield jumped between 4.2% and 4.4% late Tuesday, representing one of its fastest intraday climbs since World War II. 

    Also, on Tuesday, the first Treasury auction of three-year notes following Trump’s Liberation Day witnessed the weakest demand since late 2023.

    The drop-off for three-year notes has raised concerns about waning foreign investors’ appetite for U.S. government debt as the trade tensions escalate to what some observers see as a “once-in-a-lifetime” breakdown.

    Edited by Sebastian Sinclair

    Daily Debrief Newsletter

    Start every day with the top news stories right now, plus original features, a podcast, videos and more.


    Source link

    A Beginner’s Guide to vLLM for Quick Inference

    0
    A Beginner’s Guide to vLLM for Quick Inference


    Industries across the board are leaning heavily on large language models (LLMs) to drive innovations in everything from chatbots and virtual assistants to automated content creation and big data analysis. But here’s the kicker—traditional LLM inference engines often hit a wall when it comes to scalability, memory usage, and response time. These limitations pose real challenges for applications that need real-time results and efficient resource handling.

    This is where the need for a next-gen solution becomes critical. Imagine deploying your powerful AI models without them hogging GPU memory or slowing down during peak hours. That’s the exact problem vLLM aims to solve—with a sleek, optimised approach that redefines how LLM inference should work.

    What is vLLM?

    vLLM is a high-performance, open-source library purpose-built to accelerate the inference and deployment of large language models. It was designed with one goal in mind: to make LLM serving faster, smarter, and more efficient. It achieves this through a trio of innovative techniques—PagedAttention, Continuous Batching, and Optimised CUDA Kernels—that together supercharge throughput and minimize latency.

    What really sets vLLM apart is its support for non-contiguous memory management. Traditional engines store attention keys and values contiguously, which leads to excessive memory waste. vLLM uses PagedAttention to manage memory in smaller, dynamically allocated chunks. The result? Up to 24x faster serving throughput and efficient use of GPU resources.

    On top of that, vLLM works seamlessly with popular Hugging Face models and supports continuous batching of incoming requests. It’s plug-and-play ready for developers looking to integrate LLMs into their workflows—without needing to become experts in GPU architecture.

    Key Benefits of Using vLLM

    Open-Source and Developer-Friendly

    vLLM is fully open-source, meaning developers get complete transparency into the codebase. Want to tweak the performance? Contribute features? Or just explore how things work under the hood? You can. This open access encourages community contributions and ensures you’re never locked into a proprietary ecosystem.

    Developers can fork, modify, or integrate it as they see fit. The active developer community and extensive documentation make it easy to get started or troubleshoot issues.

    Blazing Fast Inference Performance

    Speed is one of the most compelling reasons to adopt vLLM. It’s built to maximize throughput—serving up to 24x more requests per second compared to conventional inference engines. Whether you’re running a single massive model or handling thousands of requests simultaneously, vLLM ensures your AI pipeline keeps up with demand.

    It’s perfect for applications where milliseconds matter, such as voice assistants, live customer support, or real-time content recommendation engines. Thanks to the combination of its core optimisations, vLLM delivers exceptional performance across both lightweight and heavyweight models.

    Flexibility is another huge win. vLLM supports a wide array of LLMs out of the box, including many from Hugging Face’s Transformers library. Whether you’re using Llama 3.1, Llama 3, Mistral, Mixtral-8x7B, Qwen2, or others—you’re covered. This model-agnostic design makes vLLM incredibly versatile, whether you’re running tiny models on edge devices or giant models on data centers.

    With just a few lines of code, you can load and serve your chosen model, customize performance settings, and scale it according to your needs. No need to worry about compatibility nightmares.

    Hassle-Free Deployment Process

    You don’t need a PhD in hardware optimisation to get vLLM up and running. Its architecture has been designed to minimize setup complexity and operational headaches. You can deploy and start serving models in minutes rather than hours.

    There’s extensive documentation and a library of ready-to-go tutorials for deploying some of the most popular LLMs. It abstracts away the technical heavy lifting so you can focus on building your product instead of debugging GPU configurations.

    Core Technologies Behind vLLM’s Speed

    PagedAttention: A Revolution in Memory Management

    One of the most critical bottlenecks in traditional LLM inference engines is memory usage. As models grow larger and sequence lengths increase, managing memory efficiently becomes a game of Tetris—with most solutions losing. Enter PagedAttention, a novel approach introduced by vLLM that transforms how memory is allocated and used during inference.

    How Traditional Attention Mechanisms Limit Performance

    Attention keys and values are stored contiguously in memory in typical transformer architectures. While that might sound efficient, it actually wastes a lot of space—especially when dealing with varying batch sizes or token lengths. These traditional attention mechanisms often pre-allocate memory to anticipate worst-case scenarios, leading to massive memory overhead and inefficient scaling.

    When running multiple models or handling variable-length inputs, this rigid approach results in fragmentation and unused memory blocks that could otherwise be allocated for active tasks. This ultimately limits throughput, especially on GPU-limited infrastructures.

    How PagedAttention Solves the Memory Bottleneck

    PagedAttention breaks away from the “one big memory block” mindset. Inspired by modern operating systems’ virtual memory paging systems, this algorithm allocates memory in small, non-contiguous chunks or “pages.” These pages can be reused or dynamically assigned as needed, drastically improving memory efficiency.

    Here’s why this matters:

    Reduces GPU Memory Waste: Instead of locking in large memory buffers that might not be fully used, PagedAttention allocates just what’s necessary at runtime.

    Enables Larger Context Windows: Developers can now work with longer token sequences without worrying about memory crashes or slowdowns.

    Boosts Scalability: Want to run multiple models or serve multiple users? PagedAttention scales efficiently across workloads and devices.

    By mimicking a paging system that prioritizes flexibility and efficiency, vLLM ensures that every byte of GPU memory is working toward faster inference.

    Continuous Batching: Eliminating Idle Time

    Let’s talk batching because how you handle incoming requests can make or break your system’s performance. In many traditional inference setups, batches are processed only when they are full. This “static batching” approach is easy to implement but highly inefficient, especially in dynamic real-world environments.

    Drawbacks of Static Batching in Legacy Systems

    Static batching might work fine when requests arrive in predictable, uniform waves. But in practice, traffic patterns vary. Some users send short prompts, others long. Some show up in clusters, others drip in over time. Waiting to fill a batch causes two big problems:

    Increased Latency: Requests wait around for the batch to fill up, adding unnecessary delay.

    Underutilized GPUs: During off-peak hours or irregular traffic, GPUs sit idle while waiting for batches to form.

    This approach might save on memory, but it leaves performance potential on the table.

    Advantages of Continuous Batching in vLLM

    vLLM flips the script with Continuous Batching—a dynamic system that merges incoming requests into ongoing batches in real time. There’s no more waiting for a queue to fill up; as soon as a request comes in, it’s efficiently merged into a batch that’s already in motion.

    Benefits include:

    Higher Throughput: Your GPU is always working, processing new requests without pause.

    Lower Latency: Requests get processed as soon as possible, ideal for real-time use cases like voice recognition or chatbot replies.

    Support for Diverse Workloads: Whether it’s a mix of small and large requests or high-frequency, low-latency tasks, continuous batching adapts seamlessly.

    It’s like running a conveyor belt in your GPU server—always moving, always processing, never idling.

    Optimised CUDA Kernels for Maximum GPU Utilisation

    While architectural improvements like PagedAttention and Continuous Batching make a huge difference, vLLM also dives deep into the hardware layer with optimised CUDA kernels. This secret sauce unlocks full GPU performance.

    What Are CUDA Kernels?

    CUDA (Compute Unified Device Architecture) is NVIDIA’s platform for parallel computing. Kernels are the core routines written for GPU execution. These kernels define how AI workloads are distributed and processed across thousands of GPU cores simultaneously.

    How efficiently these kernels run in AI workloads, especially LLMs, can significantly impact end-to-end performance.

    How vLLM Enhances CUDA Kernels for Better Speed

    vLLM takes CUDA to the next level by introducing tailored kernels specifically designed for inference tasks. These kernels are not just general-purpose; they’re engineered to:

    Integrate with FlashAttention and FlashInfer: These are cutting-edge methods for speeding up attention calculations. vLLM’s CUDA kernels are built to work hand-in-glove with them.

    Exploit GPU Features: Modern GPUs like the NVIDIA A100 and H100 offer advanced features like tensor cores and high-bandwidth memory access. vLLM kernels are designed to take full advantage.

    Reduce Latency in Token Generation: Optimised kernels shave milliseconds off every stage when a prompt enters the pipeline to the final token output.

    The result? A blazing-fast, end-to-end pipeline that makes the most out of your hardware investments.

    Real-World Use Cases and Applications of vLLM

    Real-Time Conversational AI and Chatbots

    Do you need your chatbot to reply in milliseconds without freezing or forgetting previous interactions? vLLM thrives in this situation. Thanks to its low latency, continuous batching, and memory-efficient processing, it’s ideal for powering conversational agents that require near-instant responses and contextual understanding.

    Whether you’re building a customer support bot or a multilingual virtual assistant, vLLM ensures that the experience remains smooth and responsive—even when handling thousands of conversations at once.

    Content Creation and Language Generation

    From blog posts and summaries to creative writing and technical documentation, vLLM is a great backend engine for AI-powered content generation tools. Its ability to quickly handle long context windows and quickly generate high-quality outputs makes it ideal for writers, marketers, and educators.

    Tools like AI copywriters and text summarization platforms can leverage vLLM to boost productivity while keeping latency low.

    Multi-Tenant AI Systems

    vLLM is perfectly suited for SaaS platforms and multi-tenant AI applications. Its continuous batching and dynamic memory management allow it to serve requests from different clients or applications without resource conflicts or delays.

    For example:

    A single vLLM server could handle tasks from a healthcare assistant, a finance chatbot, and a coding AI—all simultaneously.

    It enables smart request scheduling, model parallelism, and efficient load balancing.

    That’s the power of vLLM in a multi-user environment.

    Getting Started with vLLM

    Easy Integration with Hugging Face Transformers

    If you’ve used Hugging Face Transformers, you’ll feel right at home with vLLM. It’s been designed for seamless integration with the Hugging Face ecosystem, supporting most generative transformer models out of the box. This includes cutting-edge models like:

    Llama 3.1

    Llama 3

    Mistral

    Mixtral-8x7B

    Qwen2, and more

    The beauty lies in its plug-and-play design. With just a few lines of code, you can:

    Load your model

    Spin up a high-throughput server

    Begin serving predictions instantly

    Whether you’re working on a solo project or deploying a large-scale application, vLLM simplifies the setup process without compromising performance.

    The architecture hides the complexities of CUDA tuning, batching logic, and memory allocation. All you need to focus on is what your model needs to do—not how to make it run efficiently.

    Conclusion

    In a world where AI applications demand speed, scalability, and efficiency, vLLM emerges as a powerhouse inference engine built for the future. It reimagines how large language models should be served—leveraging smart innovations like PagedAttention, Continuous Batching, and optimised CUDA kernels to deliver exceptional throughput, low latency, and robust scalability.

    From small-scale prototypes to enterprise-grade deployments, vLLM checks all the boxes. It supports a broad range of models, integrates effortlessly with Hugging Face, and runs smoothly on top-tier GPUs like the NVIDIA A100 and H100. More importantly, it gives developers the tools to deploy and scale without needing to dive into the weeds of memory management or kernel optimization.

    If you’re looking to build faster, smarter, and more reliable AI applications, vLLM is not just an option—it’s a game-changer.

    Frequently Asked Questions

    What is vLLM?
    vLLM is an open-source inference library that accelerates large language model deployment by optimizing memory and throughput using techniques like PagedAttention and Continuous Batching.

    How does vLLM handle GPU memory more efficiently?
    vLLM uses PagedAttention, a memory management algorithm that mimics virtual memory systems by allocating memory in pages instead of one big block. This minimizes GPU memory waste and enables larger context windows.

    Which models are compatible with vLLM?
    vLLM works seamlessly with many popular Hugging Face models, including Llama 3, Mistral, Mixtral-8x7B, Qwen2, and others. It’s designed for easy integration with open-source transformer models.

    Is vLLM suitable for real-time applications like chatbots?
    Absolutely. vLLM is designed for low latency and high throughput, making it ideal for real-time tasks such as chatbots, virtual assistants, and live translation systems.

    Do I need deep hardware knowledge to use vLLM?
    Not at all. vLLM was built with usability in mind. You don’t need to be a hardware expert or GPU programmer. Its architecture simplifies deployment so you can focus on building your app.


    Source link

    Join the Birthday Airdrop: Climb the Leaderboard for Rewards and Special NFTs | NFT News Today

    Join the Birthday Airdrop: Climb the Leaderboard for Rewards and Special NFTs | NFT News Today


    My Neighbor Alice is throwing a party you won’t want to miss. This four-week extravaganza, running from April 8 to May 6, celebrates Alice’s birthday with an exciting competition, a fresh NFT Collection, and a 10K $ALICE prize pool. Whether you’re a longtime fan or just dropping by, there’s plenty of excitement to go around.

    The Party Basics

    Alice’s birthday comes with a Rewards Board jam-packed with tasks. Completing these will earn you points, and every point moves you closer to a prime spot on the leaderboard. Those who rank in the top 100 will take the biggest slice of the 10K $ALICE prize pool. Even if you miss the top tier, you can still snag rewards, so everyone has a shot at getting something special.

    Some challenges happen in-game and update weekly. You might decorate your land, try your hand at crafting NFTs, or grow fresh crops to celebrate the occasion. Other tasks push you to connect on social media—like, share, or comment on official My Neighbor Alice posts. If you feel creative, produce content that flaunts your in-game achievements or highlights Alice’s festivities, and watch your leaderboard points climb.

    Today Alice is celebrating her birthday… and you’re invited to the party! 🎂

    What does that mean? That the $ALICE Birthday Airdrop has officially begun, and from today until May 6th, you’re in for 4 weeks full of challenges, competitions, and unique rewards! 🙌

    Ready to jump… pic.twitter.com/f0ZtkGLLPU

    — Alice (@MyNeighborAlice) April 8, 2025

    How to Earn Points

    Completing in-game missions is the fastest way to climb the leaderboard. You’ll discover new objectives each week, ranging from farming activities to more advanced projects. Social media tasks appear every day, so there’s always a fresh opportunity to earn extra points by interacting with official updates.

    Inviting friends also earns you points. Refer up to 20 new neighbors, and you’ll be rewarded for helping to build a bigger community. This benefits everyone, as more players bring fresh energy and lively conversations to My Neighbor Alice.

    Game Nights offer extra chances to gain points and claim special NFTs. These events combine fun and competition, giving you a chance to meet fellow players who share your passion for virtual adventures. If you’re new, don’t worry. Start with simpler tasks like liking posts or decorating your plot. More experienced players can tackle the bigger challenges, craft unique NFTs, and pass on tips to newcomers.

    Where Fun Meets Rewards

    Alice’s birthday bash isn’t all about climbing the leaderboard. It’s also a chance to pick up commemorative digital items. A special NFT Collection will drop during the event, highlighting the festive spirit of the occasion. Each NFT doubles as a keepsake of your time celebrating with friends and competing for prizes.

    Keep an eye on the Rewards Board for daily and weekly updates. Completing a variety of making it into the coveted top 100. Even if you’re running late to the celebration, every point still matters, so feel free to join at any time before May 6.

    Stay active, invite friends, and test your skills in each challenge. Then finish strong by checking the leaderboard and enjoying the final moments of Alice’s birthday extravaganza. Let’s make this party one for the history books. Good luck, Neighbor, and may your points pile up as you join the festivities!


    Source link

    Rosie O’Donnell Cuts Troubled Daughter From $80M Estate

      0
      Rosie O’Donnell Cuts Troubled Daughter From M Estate


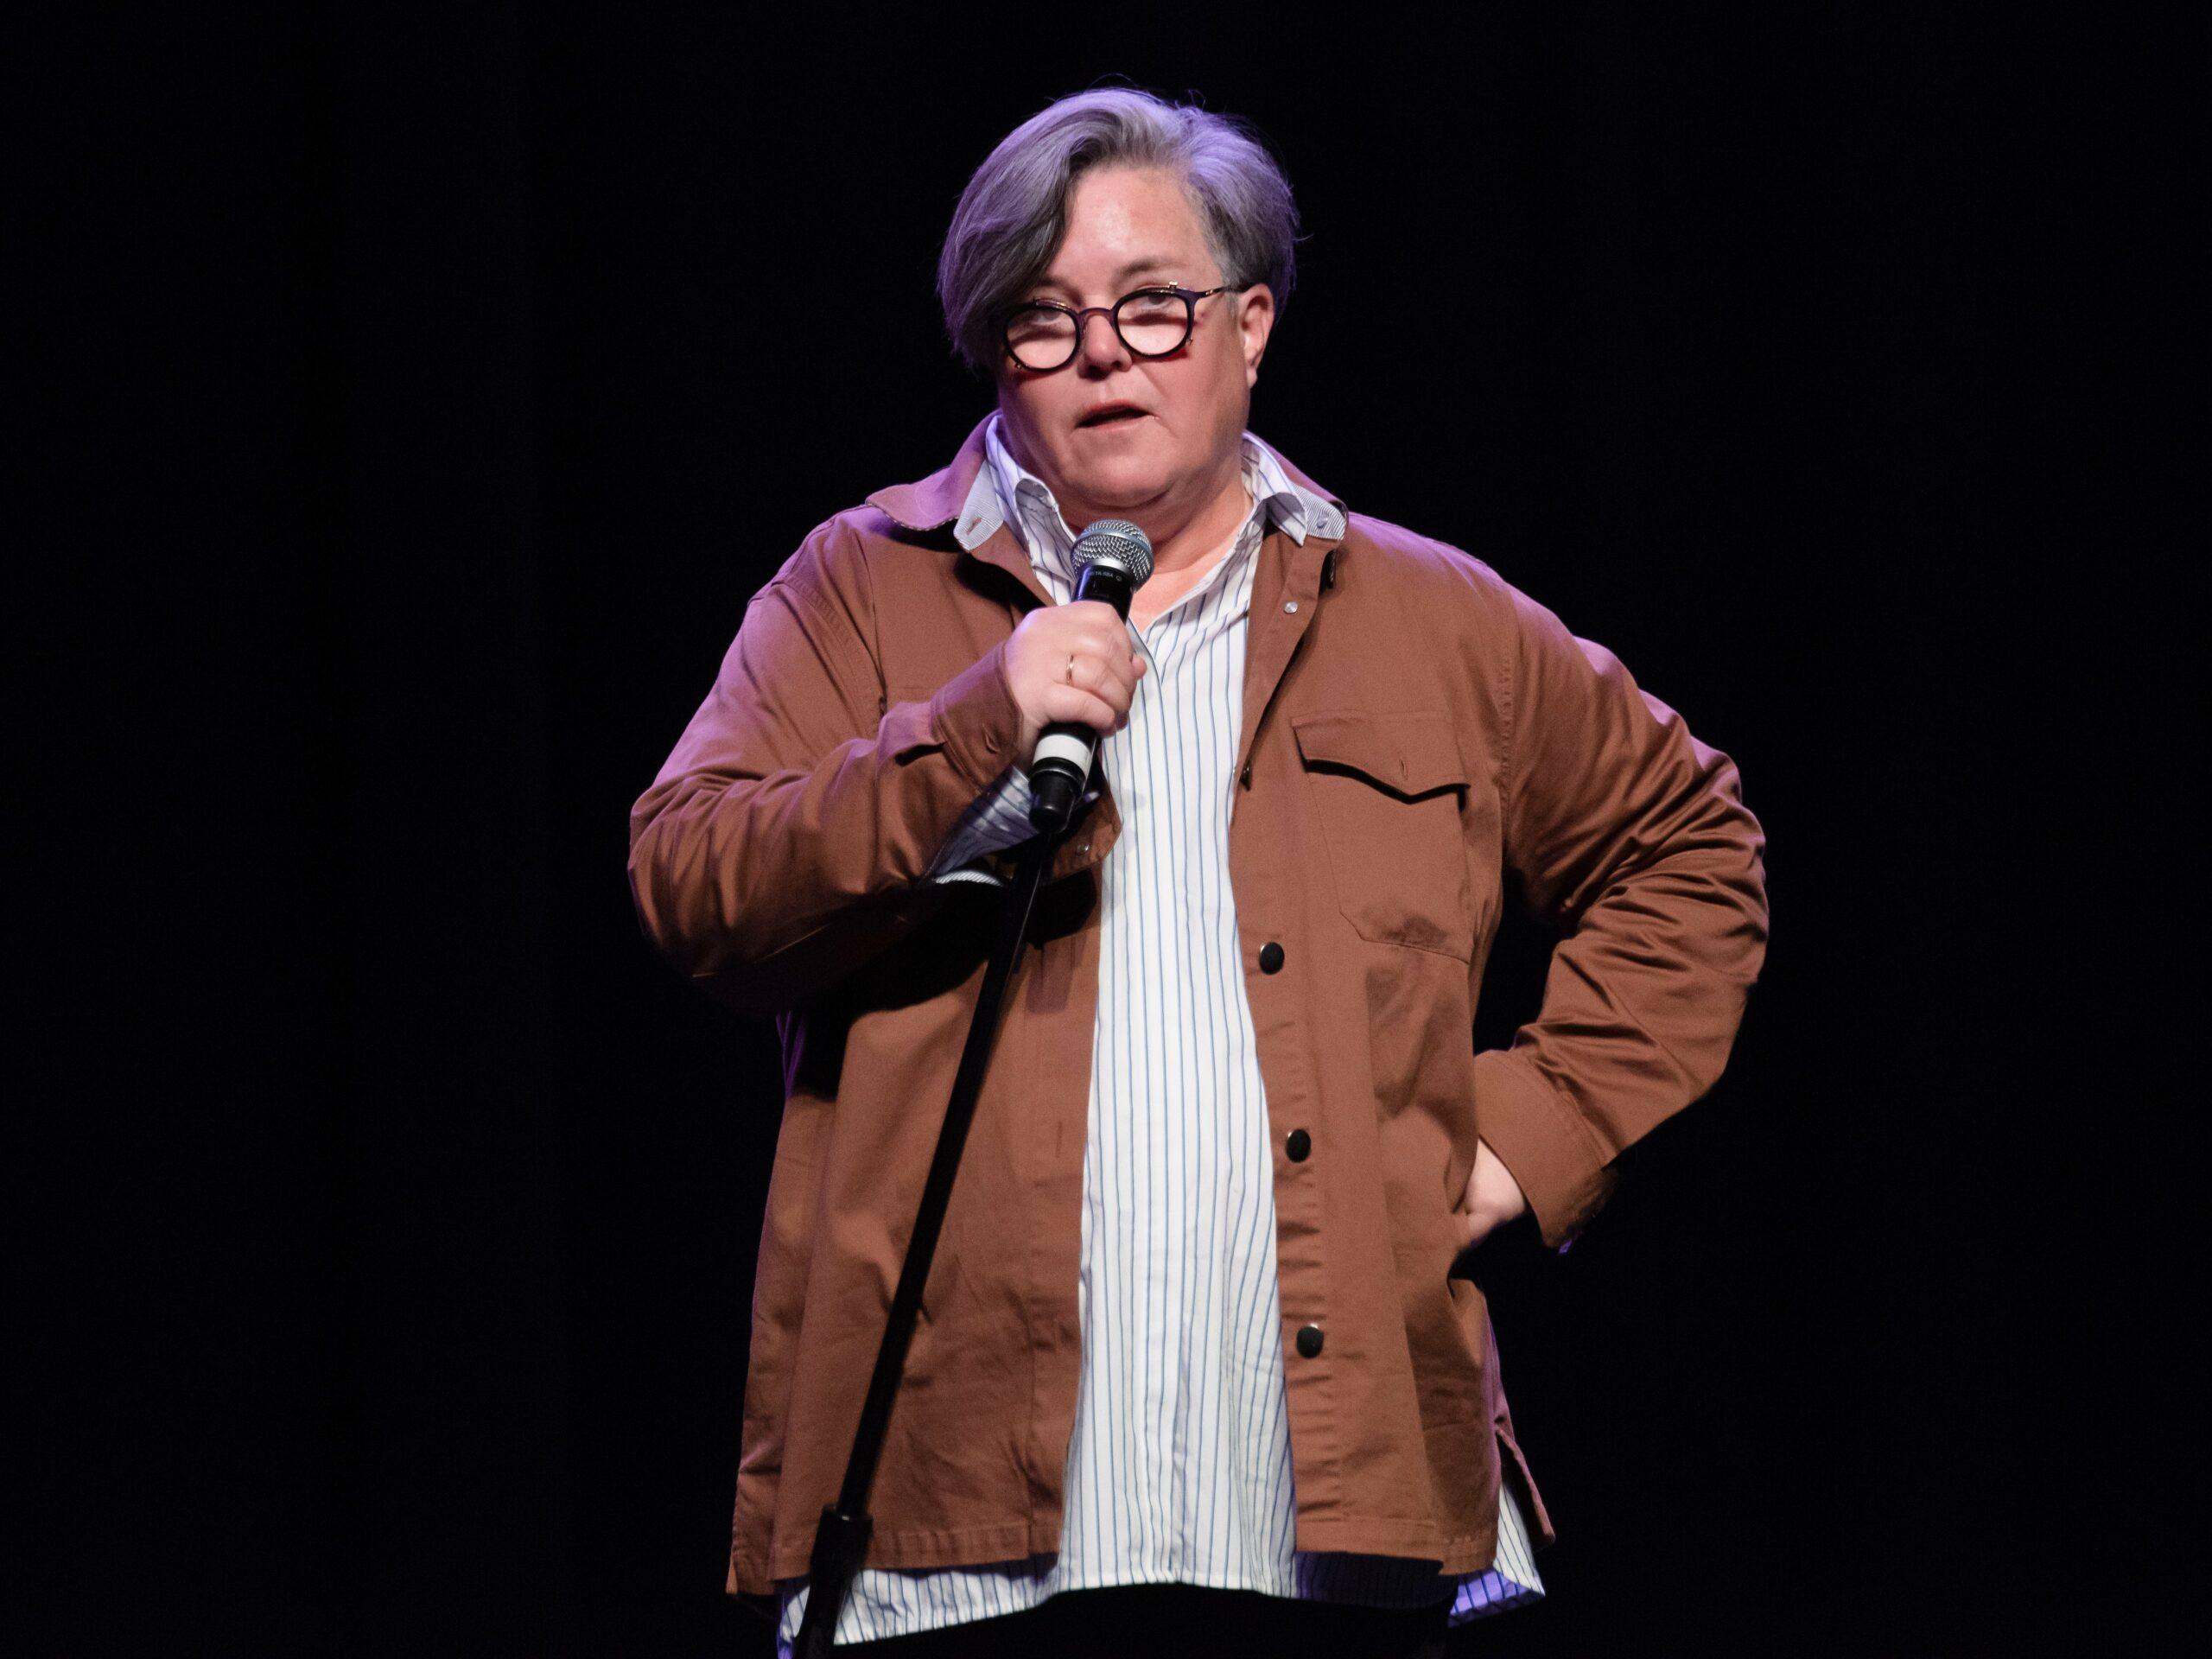
      The comedian and her daughter have had a strained relationship and reportedly don’t see eye to eye on various issues.

      Rosie O’Donnell left the country to start a new life in Ireland to protest Donald Trump’s win in the 2024 presidential election.

      Article continues below advertisement

      Rosie O’Donnell Strips Daughter Of Her Inheritance

      Mark Von Holden/ AFF-USA.com / MEGA

      According to the Daily Mail, the comedian made the decision to cut off her daughter, Chelsea, from two separate trusts days before she left the country for a new life in Ireland.

      “At the time of the execution of this indenture, the donor’s children are Parker O’Donnell, Chelsea O’Donnell (‘Chelsea’), Blake O’Donnell, Vivienne Rose O’Donnell and Dakota O’Donnell,” one of the trust documents reads.

      “However, for all purposes of this indenture, the terms of ‘the donor’s children,’ ‘child of the donor,’ ‘issue of the donor,’ and any term of like import shall not include Chelsea or any issue of Chelsea,” it continued, making clear that her grandchildren will also have no inheritance.

      Article continues below advertisement

      The news outlet further shared that Rosie ensured her estranged daughter was sent a copy of the documents so she would be aware that she had been cut from her mother’s estate, which is estimated to be worth $80 million.

      Article continues below advertisement

      Chelsea O’Donnell Files To Change Last Name

      Chelsea O'Donnell
      Instagram | Rosie O’Donnell

      Chelsea is said to be unperturbed by the development and went to court to petition to change her last name back to her birth mother, Deanna Micoley’s maiden name, Neuens.

      “Chelsea really didn’t care that Rosie wrote her out,” a source told the news outlet. “I mean who wouldn’t want to have access to millions? But for Chelsea, it is not about the money, it’s about feeling wanted and loved.”

      The source added, “And that’s something she feels she has never really had from Rosie.”

      In addition to Chelsea, Rosie also adopted four other kids: Parker, Blake, Vivienne, and Clay.

      Article continues below advertisement

      “Money is what allowed Rosie to send her away to six or seven boarding schools during her lifetime,” the source continued. “Rich people can pay someone else to raise their kids. Middle- or lower-class parents actually have to be parents, they can’t ship their kids off at the first sign of trouble.”

      Article continues below advertisement

      Why Did Rosie O’Donnell Remove Her Daughter From Her Estate?

      Rosie O'Donnell Hosts FRIENDLY HOUSE LA Comedy Benefit
      MEGA

      Although it remains unknown what caused Rosie’s decision to oust Chelsea, the 27-year-old has been battling with substance abuse and is reportedly in a sober living facility in Marinette, Wisconsin.

      According to the Daily Mail, a source shared that there may be clues in Rosie’s 30-stanza poem that she posted on Substack over the weekend.

      The free-verse poem, written almost entirely without capital letters and entitled “My Child Chelsea,” didn’t mention cutting her daughter off financially but did mention the name change.

      “She wishes to change her last name/to her birth moms maiden name/doesn’t make sense to me/ I am not her,” Rosie wrote.

      At another point, she said: “I wish I could delete my fame/for her/to make life easier/has been my goal from the beginning/but maybe that is untenable.”

      Rosie O’Donnell Hasn’t Had The Best Relationship With Her Daughter Chelsea

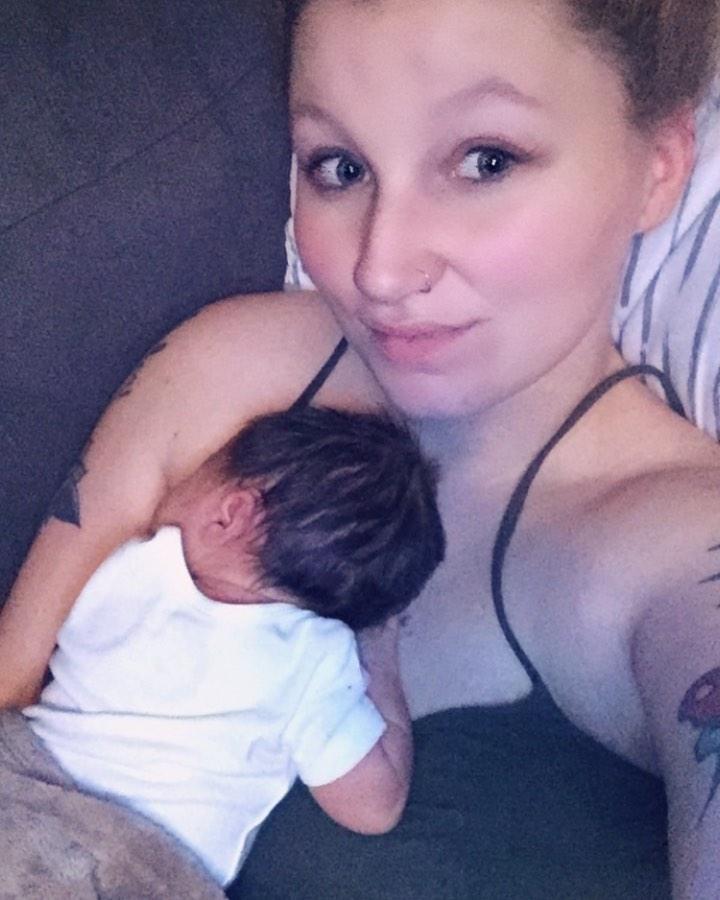
      Chelsea O'Donnell with her baby
      Instagram | Rosie O’Donnell

      Rosie’s relationship with Chelsea has seemingly been strained as the former co-host of “The View” said her daughter was “born addicted to heroin.”

      “She has had a tough road,” Rosie said in 2017 after Chelsea had given an interview to the Daily Mail claiming her mother had threatened to hit her with a wine bottle because she had gotten a tattoo.

      “Chelsea is mentally ill. Has been in and out of hospitals most of her life,” Rosie added. “She is very sick. She is not capable of truth or reason.”

      At the time, Chelsea said she was pregnant and insisted that Rosie “would not be in my son’s life,” adding that she doesn’t “feel sad about that, to be honest.”

      Article continues below advertisement

      The Comedian Fled The U.S. Over Donald Trump’s Election Victory

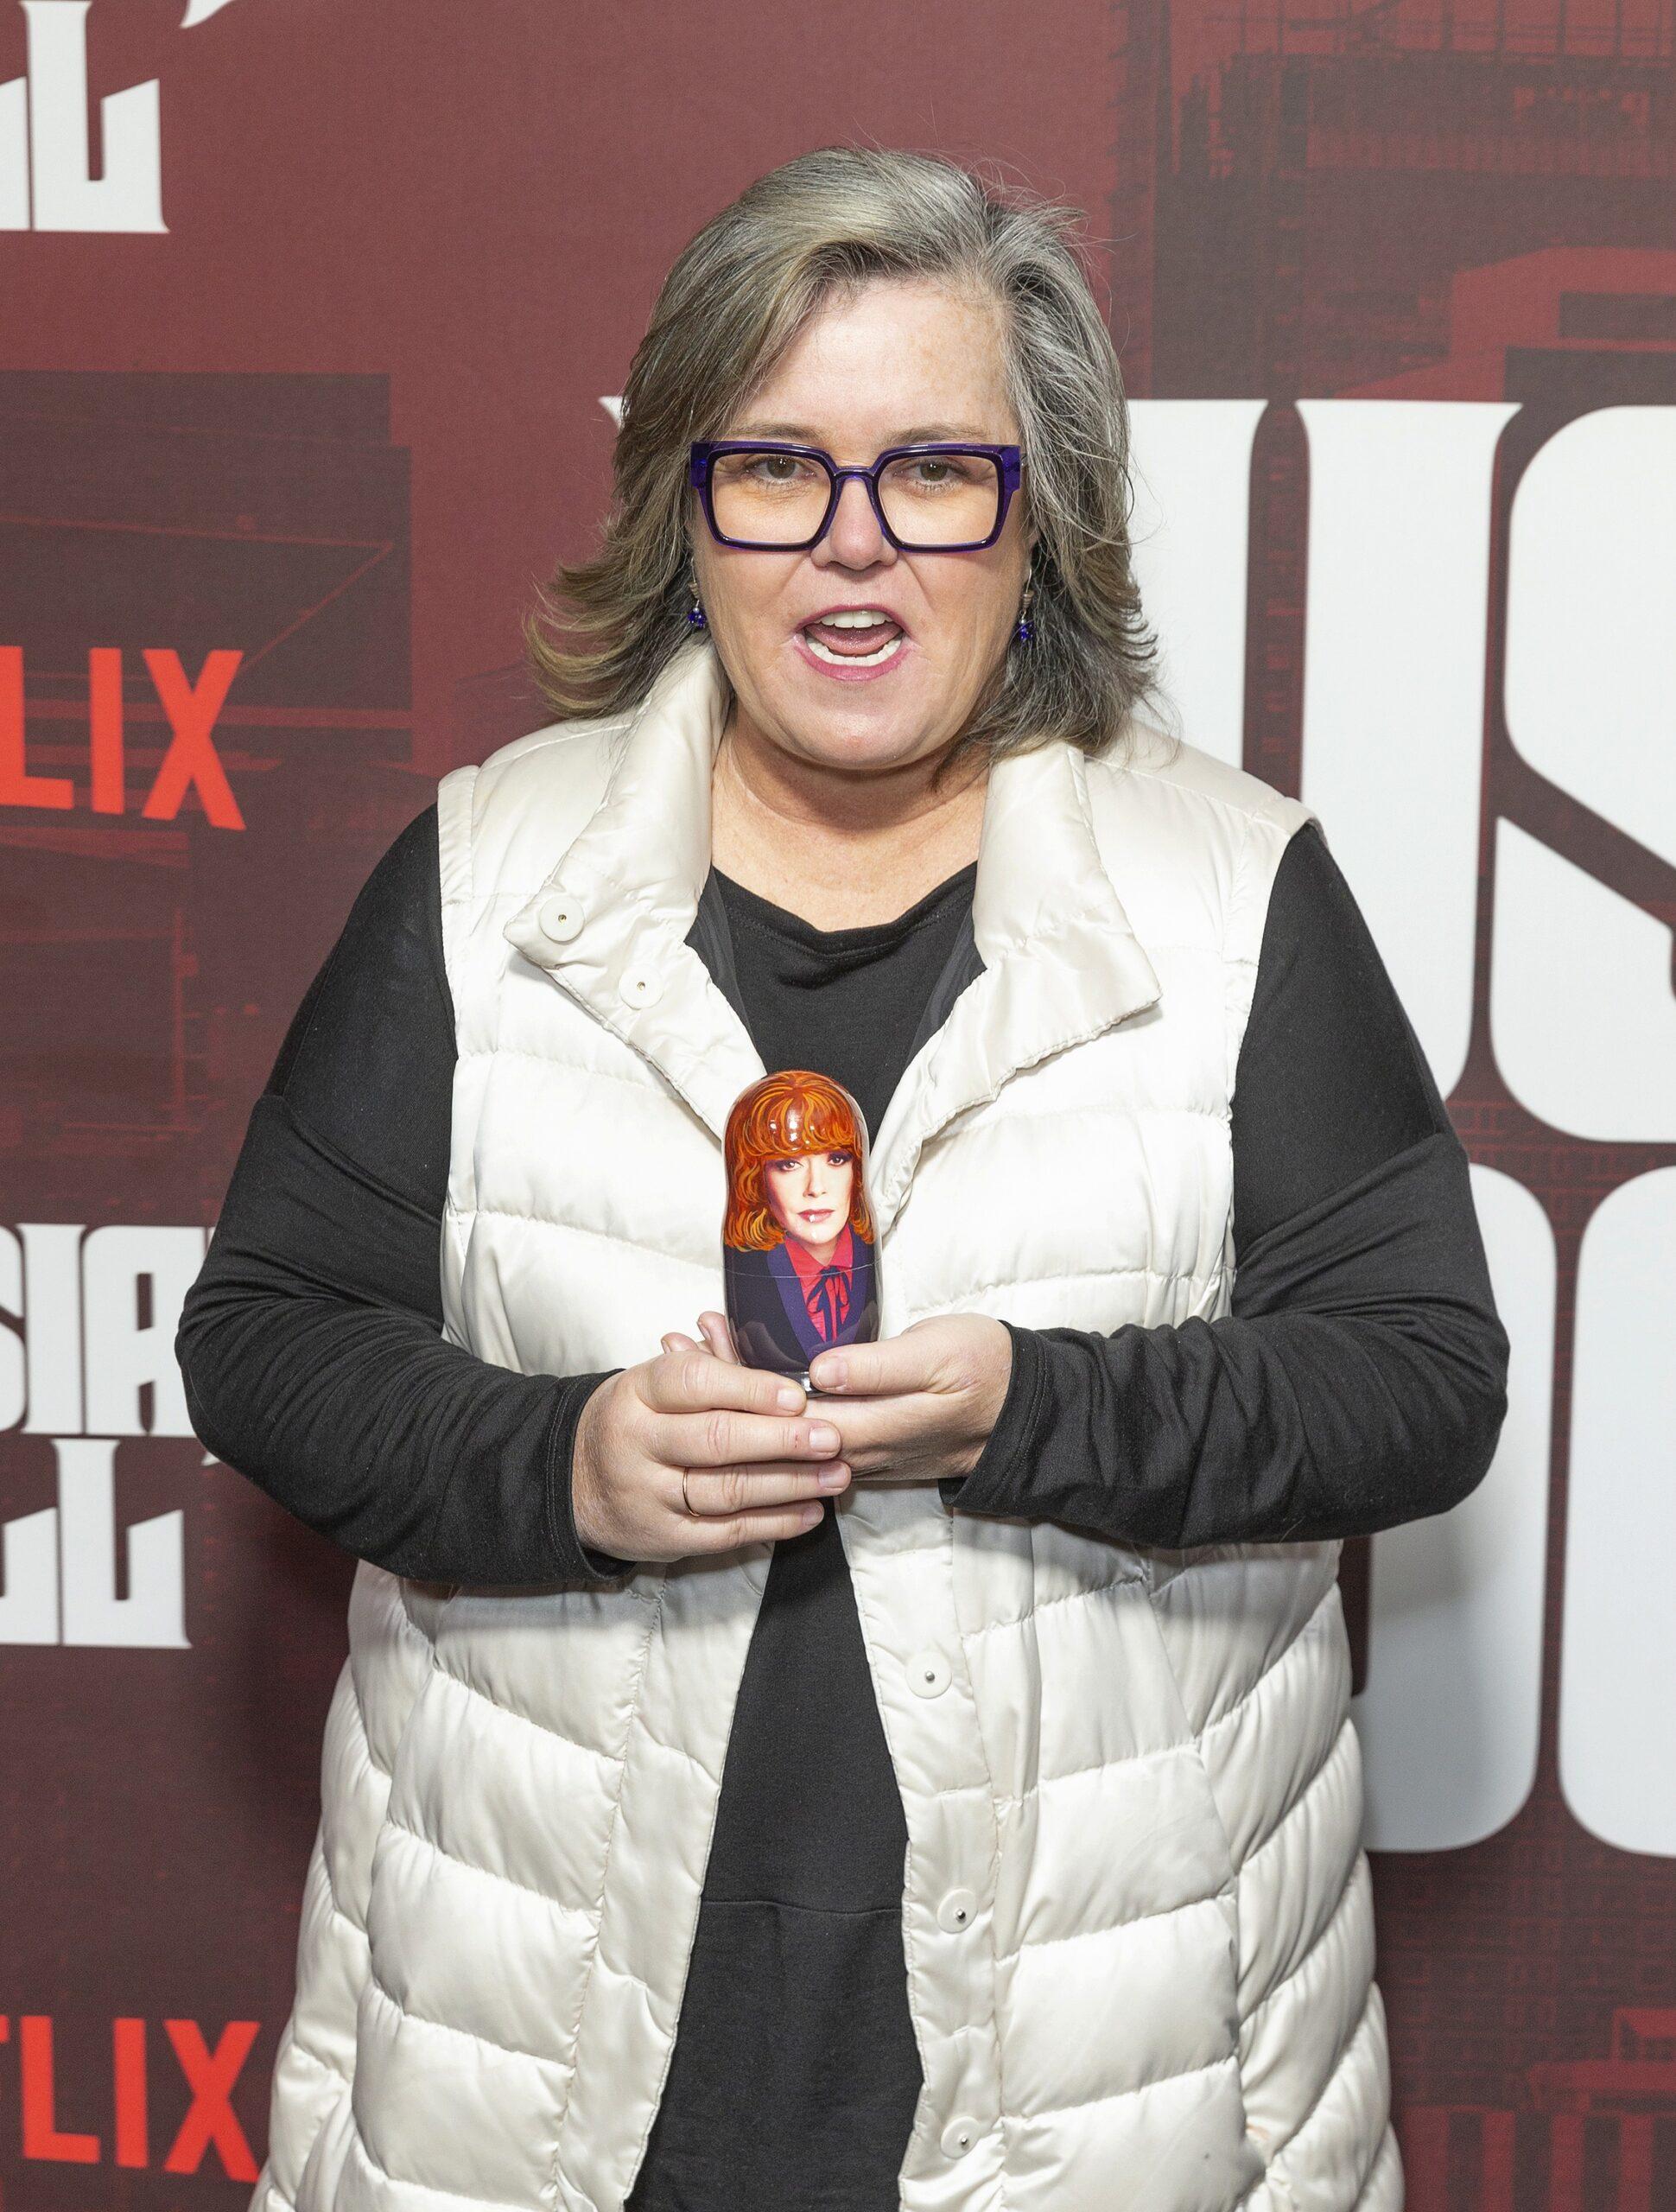
      Rosie O’Donnell at ''Russian Doll'' Season 1 Premiere-NYC
      MEGA

      Meanwhile, Rosie’s decision to cut Chelsea off comes amid her stay outside the U.S. in protest of Donald Trump’s win in the November elections.

      She says she plans to take up Irish citizenship but may return to the United States “when it is safe for all citizens to have equal rights.”

      “I miss my other kids. I miss my friends. I miss many things about life there at home, and I’m trying to find a home here in this beautiful country,” Rosie said, per the Daily Mail.

      “It’s been pretty wonderful, I have to say. The people are so loving and so kind, so welcoming. And I’m very grateful,” she added in a video on TikTok.


      Source link

      Popular Posts

      My Favorites