Home Blog Page 1142

Game On and Trade Smart- Aureal One and DexBoss Are the Presales to Beat!

0
Game On and Trade Smart- Aureal One and DexBoss Are the Presales to Beat!


Investing in the next brilliant blockchain project before everybody else knows about it – this is the whole game in crypto presales. Put your money into innovative projects as early as possible and grab tokens at a discounted price before they are available to the rest. For clever investors, it’s profit-laden, but it’s also a place with the view of tomorrow. 

This article has brought to the spotlight two of the most anticipated projects, currently making waves in their respective sectors: Aureal One and DexBoss. Both are highly awaited presales, which will feature ambitious roadmaps and strong community engagement strategies.

Aureal One: Revolutionizing Gaming and the Metaverse

Aureal One is a next-generation blockchain network that will redefine the gaming and metaverse industries. Aureal One, with its lightning-fast transaction speeds and almost negligible gas fees, is a formidable platform for developers and users alike. The native currency DLUME serves a dual purpose within the ecosystem-not only as the means of transaction for all projects hosted on the platform, thus encouraging user activity, but also as an in-game currency for different projects strung along the platform.

Click here to visit the big crypto presale – AurealOne

Aureal One: Revolutionizing Gaming and the Metaverse

Tokenomics and Presale Structure

DLUME presale consists of 21 rounds, beginning from $0.00005 in Round 1 to target raising a total of $500,000. Each of the first 20 rounds has 1 billion tokens, while the last round comprises 500 million, all at soaring prices that reach $0.0045. The presale will raise a total of $50 million, and you will get much better discounts with respect to what will be listed for $0.0055. At present value of DLUME $0.0013, and the presale is still continuing, now running the fourth round.

Community Engagement and Governance

DLUME holders can stake the tokens they own to earn rewards and vote on governance issues. These features are meant to create an active community that helps determine the future of Aureal One’s platform.

Technological Innovation

Aureal One’s standout feature is ZK rollups on the technology explicitly for use in gaming applications within the metaverse. This will not only scale transactions but also make them cost-effective as well. 

The first title released on the platform was Clash of Tiles, demonstrating the possibilities of Aureal One, but more games, such as DarkLume, are already being worked on.

Roadmap

Q4 2024: Pre-sale of DLUME tokens starts.Q1 2025: The development of Aureal One began.Q2 2025: The alpha version of Clash of Tiles was launched.Q3 2025: Token swap procedure and official launch of DLUME. 2026: Expansion into new games and applications.

DexBoss: Bridging Traditional Finance and DeFi

DexBoss allows anyone in DeFi, letting the average everyday user tackle these common points of poor liquidity, high transaction fees. It is, in essence, built around its own native token $DEBO. The platform aims to bring the next billion users into decentralized finance.

Challenges in DeFi

The challenges faced by DeFi platforms are still there, though rapid growth has marked them:

Taking away from the Bit: Learning Curve for New Users: Steeper learning curves obstruct the acceptor.Liquidity Issue: Poor liquidity means a lousy trading experience.Transaction Costs Too High: Bid colliding with profits discourages people from using it frequently.Slow Execution: Order delay in speed hurts trading opportunities.

Solution Features

DexBoss is the ultimate solution for the aforementioned problems thanks to: 

User-Friendly Interface: Easy navigation for beginners and pros alike. Deep Liquidity Pools: Reduce slippage during trades. Advanced Financial Tools: Margin trading, staking, and liquidity farming. Fast Order Execution: Near-real-time processing ensures maximum trading efficiency. Buyback and Burn Mechanism: Prolonged support for $DEBO’s long-term value.

Tokenomics and Presale Structure

DexBoss is running its presale over the course of 17 rounds, starting at $0.01 and climbing to $0.0458 during the final round, before a listing price of $0.0505. Planning to raise $50 million in the presale, it allocates 50 percent of the total 1 billion $DEBO token supply for the benefit of early investors. Currently, the price of $DEBO is $0.011, and the presale is ongoing.

Community and Governance

$DEBO enables an effortless transaction facility across the platform while offering associated benefits such as reduced trading fees, reward mechanisms, and governance participation, thus developing a long-term ecosystem that is community-driven and value-delivering.

Roadmap

Q1 2025: Opening of the presale and the marketing of $DEBO.Q2 2025: Exchange listings and platform phase one.Q3 2025: Implementation of margin trading and liquidity farming.Q4 2025: Expansion of partnerships in the fiat on/off ramp.

What Makes Them Unique?

The Zero-Knowledge Rollup integration of Aureal One makes it decidedly exceptional for scale and low-cost transactions, ideal for use in the metaverse and gaming applications. It lays great emphasis on community governance, staking, and the in-game utilization of the DLUME token. These features position Aureal One as a next-generation gaming ecosystem.DexBoss provides something different: simple DeFi that works for beginners but provides deeper liquidity and faster execution, along with margin trading and staking, promoting the value of their token through a buyback and burn scheme.

Conclusion: Why You Should Keep an Eye on Aureal One and DexBoss

Aureal One sets the pace for innovations in gaming, and DexBoss lays a track for innovations in decentralized finance. With their unique features and growing momentum, both projects have the potential to operate at a scale comparable to Bitcoin. If their trajectories continue, they could one day rival Bitcoin in recognition and influence within the crypto space.

Investigation is mandatory before any investment.


Source link

Alpha Point: Binance’s New Feature for User Activity Evaluation

0
Alpha Point: Binance’s New Feature for User Activity Evaluation


Binance has introduced Alpha Point, a novel feature designed to evaluate user engagement within the Binance Alpha ecosystem and Binance Wallet. This system rewards active users with opportunities to participate in Initial DEX Offerings (IDOs) and receive Alpha token airdrops, fostering more profound involvement in Binance’s Web3 initiatives.

What is Alpha Point?

Alpha Point is a scoring mechanism that measures user activity based on their asset holdings and trading behavior. It determines eligibility for exclusive events like IDOs and airdrops, incentivizing users to stay active in the Binance ecosystem.

Binance launched this feature to prioritize dedicated users, ensuring that rewards such as early token access go to those who contribute significantly to the platform’s growth. By introducing Alpha Point, Binance aims to create a fair yet competitive environment, encouraging users to engage more deeply with its Web3 offerings.

binance-logo-2

How to Calculate Alpha Point?

Alpha Points are updated daily before 1:00 PM and calculated using two key metrics over 15 days:

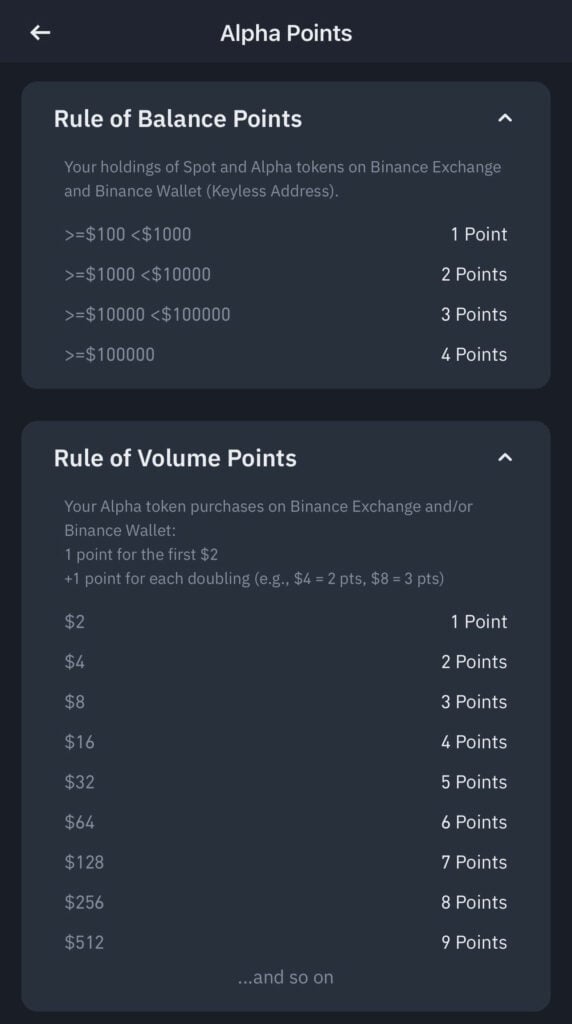
Balance Points (Hold): Binance users will receive points based on the total balance of spot tokens and Alpha in their account and Binance Wallet. For example, a balance of $100–$1,000 earns 1 point, while $100,000 or more earns 4 points.

Read more: How to participate IDO on Binance Wallet

Volume Points (Volume): Points are granted for buying Alpha tokens on the exchange or wallet. The formula starts with 1 point for the first $2, adding 1 point for each doubling of the amount (e.g., $8 earns 3 points, $1,024 earns 10 points). Selling Alpha tokens does not contribute to the score.

How to Calculate Alpha Point?How to Calculate Alpha Point?

Source: Binance Exchange

Total Alpha Points combine both balance and purchase points, motivating users to maintain high balances and actively trade Alpha tokens.

Most recently, Binance has announced the listing of $SIGN (Ethsign) on Binance Alpha. Besides, users can receive the $SIGN airdrop when they meet the required points on Alpha Point. The exact amount of Alpha points will be disclosed later, on April 28.

How to Check Alpha Points on the Binance App

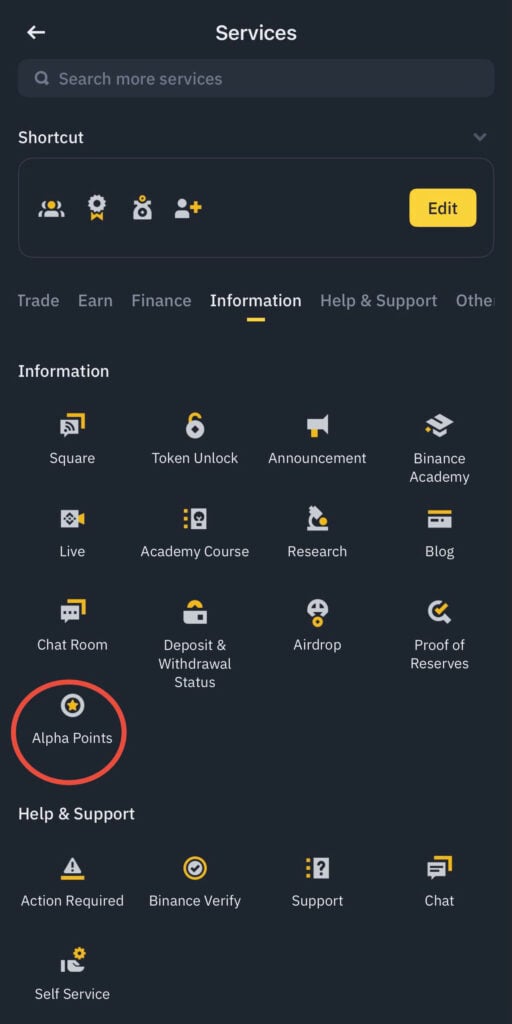
Checking Alpha Points is straightforward. Open the Binance app, navigate to “More services,” scroll to the “Information” section, and select “Alpha Points.”

How to Check Alpha Points on the Binance AppHow to Check Alpha Points on the Binance App

Source: Binance Exchange

This feature allows users to monitor their scores and adjust their strategies to maximize points. Essentially, Alpha Point is Binance’s way of filtering out truly committed users, prioritizing them for token launches and airdrop distributions. It rewards those who invest time and resources into the platform, aligning benefits with engagement.

Learn more: How to participate in Hyperlane presale on Binance Wallet

For those aiming to secure a spot in IDOs or airdrops, starting to accumulate points early is crucial. As the Alpha Point system evolves, its requirements may become stricter, making proactive participation essential. By maintaining at least a $100 balance, purchasing Alpha tokens, and regularly checking scores, users can position themselves for future opportunities in Binance’s expanding Web3 ecosystem.


Source link

Comparing LLM Fine-Tuning Frameworks: Axolotl, Unsloth, and Torchtune

0
Comparing LLM Fine-Tuning Frameworks: Axolotl, Unsloth, and Torchtune


Large Language Models (LLMs) continue to transform research workflows and production pipelines. While the capabilities of base models improve rapidly, fine-tuning remains an indispensable process for tailoring these powerful tools to specific needs. Fine-tuning bridges the gap between a model’s vast general knowledge and the specialized requirements of particular tasks or domains. This adaptation unlocks significant benefits, including higher accuracy on targeted tasks, better alignment with desired outputs or safety guidelines, enhanced relevance within specific domains, and greater control over the model’s style and format, such as adhering to a company’s tone of voice.

Furthermore, fine-tuning can teach models domain-specific terminology, reduce the frequency of hallucinations in critical applications, and even optimize latency by creating smaller, specialized models derived from larger ones. Compared to the immense cost of training models from scratch, fine-tuning leverages the pre-existing knowledge embedded in base models, drastically reducing computational requirements and training time. The growing emphasis on fine-tuning signals a maturation in the field, moving beyond generic, off-the-shelf models to create more customized, efficient, and task-specific AI solutions.

Why Choosing the Right Framework Matters

As fine-tuning becomes more widespread, choosing the software framework for managing this process becomes critically important. The proper fine-tuning framework can significantly impact performance metrics like training speed and throughput, resource utilization, particularly Graphics Processing Unit (GPU) Video RAM (VRAM), and ease of experimentation and development.

Different frameworks embody distinct design philosophies and prioritize different aspects, leading to inherent trade-offs. Some emphasize flexibility and broad compatibility, others focus on raw speed and memory efficiency, while some prioritize deep integration with specific ecosystems. These trade-offs mirror fundamental choices in software development, highlighting that selecting a fine-tuning framework requires careful consideration of project goals, available hardware, team expertise, and desired scalability.

Introducing the Contenders: Axolotl, Unsloth, and Torchtune

By 2025, several powerful frameworks will have emerged as popular choices for LLM fine-tuning. Among the leading contenders are Axolotl, Unsloth, and Torchtune. Each offers a distinct approach and set of advantages:

Axolotl is widely recognized for its flexibility, ease of use, community support, and rapid adoption of new open-source models and techniques.

Unsloth has carved out a niche as the champion of speed and memory efficiency, particularly for users with limited GPU resources.

Torchtune, the official PyTorch library, provides deep integration with the PyTorch ecosystem, emphasizing extensibility, customization, and robust scalability.

This article explores how these toolkits handle key considerations like training throughput, VRAM efficiency, model support, feature sets, multi-GPU scaling, ease of setup, and deployment pathways. The analysis aims to provide ML practitioners, developers, and researchers with the insights needed to select the framework that best aligns with their specific fine-tuning requirements in 2025.

Note on Experimentation: Accessing GPU Resources via Spheron

Evaluating and experimenting with these frameworks often requires access to capable GPU hardware. Users looking to conduct their fine-tuning experiments and benchmark these frameworks can rent GPUs from Spheron, providing a practical avenue to apply this article’s findings.

Axolotl is a free, open-source tool dedicated to streamlining the post-training lifecycle of AI models.8 This encompasses a range of techniques beyond simple fine-tuning, including parameter-efficient fine-tuning (PEFT) methods like LoRA and QLoRA, supervised fine-tuning (SFT), instruction tuning, and alignment. The framework’s core philosophy centers on making these powerful techniques accessible, scalable, and user-friendly, fostering a collaborative environment described as “fun.”.

Axolotl achieves this through strong community engagement (active Discord, numerous contributors) and a focus on ease of use, providing pre-existing configurations and examples that allow users to start training quickly. Its target audience is broad, encompassing beginners seeking a gentle introduction to fine-tuning, researchers experimenting with diverse models and techniques, AI platforms needing flexible integration, and enterprises requiring scalable solutions they can deploy in their environments (e.g., private cloud, Docker, Kubernetes). The framework has earned trust from notable research groups and platforms like Teknium/Nous Research, Modal, Replicate, and OpenPipe. Configuration is managed primarily through simple YAML files, which define everything from dataset preprocessing and model selection to training parameters and evaluation steps.

Performance Deep Dive: Benchmarks and Characteristics

Axolotl delivers solid fine-tuning performance by incorporating established best practices. It integrates optimizations like FlashAttention for efficient attention computation, gradient checkpointing to save memory, and defaults tuned for memory efficiency. It also supports multipacking (packing multiple short sequences into one) and RoPE scaling for handling different context lengths. For specific models like Gemma-3, it integrates specialized optimizations like the Liger kernel.

Compared directly to the other frameworks, Axolotl’s use of abstraction layers wrapping Hugging Face Transformers libraries can sometimes result in slightly slower training speeds. However, independent benchmarks comparing it against TorchTune (with torch. compile enabled) found Axolotl to be only marginally slower (around 3%) in a specific LoRA fine-tuning task. This suggests that while some overhead exists, it may not be a significant bottleneck for all workloads, especially considering Axolotl’s flexibility and feature breadth. Furthermore, Axolotl supports the torch_compile flag, potentially closing this gap further where applicable.

Model Universe and Recent Additions (LLaMA 4, Gemma-3, Multimodal)

A key strength of Axolotl is its extensive and rapidly expanding support for various model architectures. It is designed to work with many models available through Hugging Face. Supported families include Llama, Mistral, Mixtral (including MoE variants), Pythia (EleutherAI), Falcon (Technology Innovation Institute), MPT (MosaicML), Gemma (Google DeepMind), Phi (Microsoft Research), Qwen (Alibaba), Cerebras (Cerebras Systems), XGen (Salesforce), RWKV (BlinkDL), BTLM (Together), GPT-J (EleutherAI), and Jamba (AI21 Labs). Axolotl has gained a reputation for quickly adding support for newly released open-source models.

Recent releases (v0.8. x in 2025) reflected this agility and incorporated support for Meta’s LLaMA 3 and the newer LLaMA 4 models, including the LLaMA 4 Multimodal variant.11 Support for Google’s Gemma-3 series and Microsoft’s Phi-2/Phi-3 models was also added.11 This commitment ensures users can leverage the latest advancements in open LLMs shortly after release.

Beyond text-only models, Axolotl has ventured into multimodal capabilities. It introduced a beta for multimodal fine-tuning, providing built-in recipes and configurations for popular vision-and-language models such as LLaVA-1.5, “Mistral-Small-3.1” vision, MLLama, Pixtral, and Gemma-3 Vision. This expansion addresses the growing interest in models that can process and integrate information from multiple modalities.

Feature Spotlight: Sequence Parallelism for Long Context, Configuration Ease

Axolotl continuously integrates cutting-edge features to enhance fine-tuning capabilities. Two notable areas are its approach to long-context training and its configuration system.

Long Context via Sequence Parallelism: Training models on very long sequences (e.g., 32k tokens or more) poses significant memory challenges due to the quadratic scaling of attention mechanisms. Axolotl addresses this critical need by implementing sequence parallelism (SP), leveraging the ring-flash-attn library. Sequence parallelism works by partitioning a single long input sequence across multiple GPUs; each GPU processes only a sequence segment.

This distribution directly tackles the memory bottleneck associated with sequence length, allowing for near-linear scaling of context length with the number of GPUs and enabling training runs that would otherwise be impossible on a single device. This SP implementation complements Axolotl’s existing multi-GPU strategies like FSDP and DeepSpeed. Configuring SP is straightforward via a sequence_parallel_degree parameter in the YAML file. However, it requires Flash Attention to be enabled and imposes certain constraints on batch size and the relationship between SP degree, GPU count, sequence length, and attention heads. The integration of SP reflects Axolotl’s ability to quickly adopt advanced techniques emerging from the research community, addressing the increasing demand for models capable of processing extensive context windows.

Ease of Configuration and Other Features: Axolotl maintains its user-friendly approach through simple YAML configuration files, which are easily customized or augmented with command-line overrides.8 Recent refinements include support for custom tokenizer settings, such as defining reserved tokens.11 The project also provides “Cookbooks,” offering templates for everyday tasks, like the whimsical “talk like a pirate” example. Community projects have developed UI wrappers for Axolotl for users seeking a graphical interface.19 Other notable features added in 2025 include support for the REX learning rate scheduler (potentially for faster convergence), cut-cosine cross-entropy (CCE) loss (improving stability for models like Cohere or Gemma), the specialized Liger kernel for efficient Gemma-3 fine-tuning, and integration with distributed vLLM servers to accelerate data generation during RLHF loops.

The framework’s strength in rapidly integrating community advancements positions it as a dynamic hub for leveraging the latest open-source innovations. This agility allows users to experiment with new models and techniques that are emerging quickly.

Scaling Capabilities: Multi-GPU and Distributed Training Mastery

Multi-GPU training is highlighted as a core strength of Axolotl. It offers robust support for various distributed training strategies, catering to different needs and hardware setups:

DeepSpeed: Recommended for its stability and performance, Axolotl supports ZeRO stages 1, 2, and 3, providing varying levels of memory optimization. Default configurations are provided.

Fully Sharded Data Parallel (FSDP): Axolotl supports PyTorch’s FSDP and is working towards adopting FSDP v2.8. Configuration options allow for features like CPU offloading.

Sequence Parallelism: As detailed above, SP adds another dimension to Axolotl’s scaling capabilities, specifically for handling long sequences across multiple GPUs.

This comprehensive support for distributed training enables users to tackle large-scale fine-tuning tasks. Numerous users have successfully fine-tuned models with tens of billions of parameters (e.g., 65B/70B Llama models) using Axolotl across multiple high-end GPUs like NVIDIA A100s. The framework also supports multi-node training, allowing jobs to span multiple machines. This combination of mature distributed strategies (DeepSpeed, FSDP) and targeted optimizations for sequence length (SP) makes Axolotl a powerful open-source choice for pushing the boundaries of model size and context length.

Ecosystem Integration and Deployment Pathways

Axolotl integrates seamlessly with various tools and platforms within the MLOps ecosystem. It supports logging to Weights & Biases (W&B), MLflow, and Comet for experiment tracking and visualization.8 It is designed to run effectively on cloud platforms and infrastructure providers, with documented integrations or user communities utilizing Runpod, Latitude, Modal, Jarvislabs, and SkyPilot. Its foundation relies heavily on the Hugging Face ecosystem, particularly the Transformers and Datasets libraries.

Once a model is fine-tuned, Axolotl facilitates deployment by allowing models to be exported into the standard Hugging Face format. These models can then be served using popular inference engines like vLLM. While the reliance on YAML for configuration promotes simplicity for everyday use cases, it might present challenges for highly complex or experimental setups requiring fine-grained programmatic control, potentially limiting deep customization compared to more code-centric frameworks.8

Unsloth: The Speed and Efficiency Champion

Unsloth enters the fine-tuning arena with a laser focus on optimizing performance, specifically targeting training speed and VRAM efficiency. Its primary goal is to make fine-tuning accessible even for users with limited hardware resources, democratizing the ability to customize powerful LLMs.3

The core of Unsloth’s advantage lies not in approximation techniques but in meticulous low-level optimization. The team achieves significant speedups and memory reduction through custom-written GPU kernels using OpenAI’s Triton language, a manual backpropagation engine, and other techniques like optimized matrix multiplication. Unsloth claims these gains come with 0% loss in accuracy for standard LoRA and QLoRA fine-tuning compared to baseline implementations. This focus on exactness distinguishes it from methods that might trade accuracy for speed.

Its target audience primarily includes hardware-constrained users, such as those utilizing single consumer-grade GPUs (like NVIDIA RTX 4090s or 3090s) or free cloud tiers like Google Colab, which often provide older GPUs like the Tesla T4. However, its impressive performance has also attracted major industry players, including Microsoft, NVIDIA, Meta, NASA, HP, VMware, and Intel, indicating its value extends beyond resource-constrained scenarios.

Performance Deep Dive: Unpacking the Speed and VRAM Claims (OSS vs. Pro)

Unsloth makes bold claims about its performance, differentiating between its free open-source offering and commercial Pro/Enterprise tiers.

Open Source (OSS) Performance: The free version promises substantial improvements for single-GPU fine-tuning. Reports indicate 2- 5x faster training speeds and up to 80% less VRAM consumption than standard baselines using Hugging Face Transformers with FlashAttention 2 (FA2). Specific examples include fine-tuning Llama 3.2 3B 2x faster with 70% less memory, or Gemma 3 4B 1.6x faster with 60% less memory. This VRAM efficiency directly translates to the ability to train larger models, use larger batch sizes, or handle significantly longer context windows on memory-limited GPUs.

Pro/Enterprise Performance: Unsloth offers premium tiers with even more dramatic performance enhancements. The “Pro” version reportedly achieves around 10x faster training on a single GPU and up to 30x faster on multi-GPU setups, coupled with 90% memory reduction versus FA2. The “Enterprise” tier pushes this further to 32x faster on multi-GPU/multi-node clusters. These paid versions may also yield accuracy improvements (“up to +30%”) in specific scenarios and offer faster inference capabilities (5x claimed for Enterprise).

Independent Benchmarks: Third-party benchmarks generally corroborate Unsloth’s single-GPU advantage. One comparison found Unsloth to be 23-24% faster than Torchtune (with torch.compile) on an RTX 4090, using ~18% less VRAM. On an older RTX 3090, the advantage was even more pronounced: ~27-28% faster and ~17% less VRAM. These results confirm Unsloth’s significant edge in single-GPU scenarios.

Hardware and Software Support: The open-source version primarily supports NVIDIA GPUs with CUDA Capability 7.0 or higher (V100, T4, RTX 20xx series and newer). While portability to AMD and Intel GPUs is mentioned as a goal, NVIDIA remains the focus.6 Unsloth works on Linux and Windows, although Windows usage might require specific setup steps or workarounds, such as installing a Triton fork and adjusting dataset processing settings.5 Python 3.10, 3.11, and 3.12 are supported, but not 3.

Model Universe and Recent Additions (LLaMA 4 Variants, Gemma 3, Vision)

Unsloth supports a curated list of popular and recent LLM architectures, focusing on those widely used in the community. While not as exhaustive as Axolotl’s list, it covers many mainstream choices. Supported families include Llama (versions 1, 2, 3, 3.1, 3.2, 3.3, and the new Llama 4), Gemma (including Gemma 3), Mistral (v0.3, Small 22b), Phi (Phi-3, Phi-4), Qwen (Qwen 2.5, including Coder and VL variants), DeepSeek (V3, R1), Mixtral, other Mixture-of-Experts (MoE) models, Cohere, and Mamba.

Keeping pace with releases in 2025, Unsloth added support for Meta’s Llama 4 models, specifically the Scout (17B, 16 experts) and Maverick (17B, 128 experts) variants, demonstrating strong performance rivaling models like GPT-4o. It also supports Google’s Gemma 3 family (1B, 4B, 12B, 27B), Microsoft’s Phi-4 5, Alibaba’s Qwen 2.5 5, and Meta’s Llama 3.3 70 B. Unsloth often provides pre-optimized 4-bit and 16-bit versions of these models directly on Hugging Face for immediate use.

Unsloth has also embraced multimodal fine-tuning, adding support for Vision Language Models (VLMs). This includes models like Llama 3.2 Vision (11B), Qwen 2.5 VL (7B), and Pixtral (12B) 2409.

Feature Spotlight: Custom Kernels, Dynamic Quantization, GRPO, Developer Experience

Unsloth differentiates itself through several key features stemming from its optimization focus and commitment to usability.

Custom Kernels: The foundation of Unsloth’s performance lies in its hand-written GPU kernels developed using OpenAI’s Triton language. By creating bespoke implementations for compute-intensive operations like attention and matrix multiplications, Unsloth bypasses the overhead associated with more general-purpose library functions, leading to significant speedups.

Dynamic Quantization: To further improve memory efficiency, Unsloth introduced an “ultra-low precision” dynamic quantization technique capable of quantizing down to 1.58 bits. This method intelligently chooses not to quantize certain parameters, aiming to preserve accuracy while maximizing memory savings. Unsloth claims this technique uses less than 10% more VRAM than standard 4-bit quantization while increasing accuracy. This technique is particularly useful for inference or adapter-based training methods like LoRA/QLoRA.

Advanced Fine-Tuning Techniques: Beyond standard LoRA and QLoRA (which it supports with 4-bit and 16-bit precision via bitsandbytes integration), Unsloth incorporates advanced techniques. It supports Rank-Stabilized LoRA (RSLORA) and LoftQ to improve LoRA training stability and better integrate quantization. It also supports GRPO (Generalized Reward Process Optimization), a technique for enhancing the reasoning capabilities of LLMs. Unsloth provides tutorials on transforming models like Llama or Phi into reasoning LLMs using GRPO, even with limited VRAM (e.g., 5GB). Furthermore, Unsloth supports full fine-tuning, 8-bit training, and continued pretraining modes.

Long Context Support: Unsloth has beta support for long-context training and reasoning. Its inherent VRAM efficiency allows users to train models with significantly longer sequence lengths on given hardware compared to standard frameworks using FlashAttention 2.5. For example, benchmarks show Llama 3.1 8B reaching over 342k context length on an 80GB GPU with Unsloth, compared to ~28k with HF+FA2.

Developer Experience: Despite its sophisticated backend, Unsloth prioritizes ease of use, particularly for beginners.3 It provides readily available Google Colab and Kaggle notebooks, allowing users to start fine-tuning quickly with free GPU access.3 It offers a high-level Python API, notably the FastLanguageModel wrapper, which enables fine-tuning setup in just a few lines of code.33 Configuration is typically done via simple Python scripts rather than complex YAML files.12 The project maintains comprehensive documentation, tutorials, and an active, responsive team presence on platforms like Discord and Reddit.12 This combination of performance and usability makes Unsloth an attractive entry point for users new to fine-tuning.

Scaling Capabilities: Single-GPU Focus (OSS) vs. Multi-GPU/Node (Pro/Enterprise)

A crucial distinction exists between UnSloth’s open-source and commercial offerings regarding scalability.

Open Source (OSS): The free, open-source version of Unsloth is explicitly and primarily designed for single-GPU training. As of early to mid-2025, multi-GPU support is not officially included in the OSS version, although it is frequently mentioned as being on the roadmap or planned for a future release. This limitation is a key differentiator compared to Axolotl and Torchtune, which offer open-source multi-GPU capabilities. While some users have explored workarounds using tools like Hugging Face Accelerate or Llama Factory, these are not officially supported paths.

Pro/Enterprise: Multi-GPU and multi-node scaling are premium features reserved for Unsloth’s paid tiers.6 The Pro plan unlocks multi-GPU support (reportedly up to 8 GPUs), while the Enterprise plan adds multi-node capabilities, allowing training to scale across clusters of machines. This tiered approach means users needing to scale beyond a single GPU must engage with Unsloth’s commercial offerings. This focus on optimizing for the large single-GPU user base in the free tier, while monetizing advanced scaling, represents a clear strategic choice.

Ecosystem Integration and Industry Adoption

Unsloth integrates well with key components of the LLM development ecosystem. It works closely with Hugging Face, utilizing its models and datasets, and is referenced within the Hugging Face TRL (Transformer Reinforcement Learning) library documentation. It integrates with Weights & Biases for experiment tracking and relies on libraries like bitsandbytes for quantization functionalities.

Unsloth facilitates exporting fine-tuned models into popular formats compatible with various inference engines for deployment. This includes GGUF (for CPU-based inference using llama.cpp), Ollama (for easy local deployment), and VLLM (a high-throughput GPU inference server).

Unsloth has gained significant traction and recognition within the AI community. It received funding from notable investors like Microsoft’s M12 venture fund and the GitHub Open Source Fund. Its user base includes prominent technology companies and research institutions, highlighting its adoption beyond individual developers. It stands out as one of the fastest-growing open-source projects in the AI fine-tuning space. However, the gating of multi-GPU/node support behind paid tiers presents a potential friction point with parts of the open-source community and raises considerations about the long-term feature parity between the free and commercial versions, especially given the small core team size.

Torchtune: The Native PyTorch Powerhouse

Torchtune emerges as the official PyTorch library dedicated to fine-tuning LLMs. Its design philosophy is deeply rooted in the PyTorch ecosystem, emphasizing a “native PyTorch” approach. This translates to a lean, extensible library with minimal abstractions – explicitly avoiding high-level wrappers like “trainers” or imposing rigid framework structures. Instead, it provides composable and modular building blocks that align closely with standard PyTorch practices.

This design choice targets a specific audience: users who are already comfortable and proficient with PyTorch and prefer working directly with its core components. This includes researchers, developers, and engineers requiring deep customization, flexibility, and extensibility in fine-tuning workflows. The transparency offered by this “just PyTorch” approach facilitates easier debugging and modification compared to more heavily abstracted frameworks. While powerful for experienced users, this native philosophy might present a steeper learning curve for those less familiar with PyTorch internals than Axolotl or Unsloth’s guided approaches.

Performance Deep Dive: Leveraging PyTorch Optimizations (TorchCompile)

Torchtune aims for excellent training throughput by directly leveraging the latest performance features within PyTorch 2.x.7 Key optimizations include using the torch. Compile to fuse operations and optimize execution graphs, native support for efficient attention mechanisms like FlashAttention, and other fused operations available in PyTorch.7 The pure PyTorch design ensures minimal framework overhead.

A significant performance lever is torch.compile. Users can activate this powerful optimization by setting compile: True in the configuration YAML files. While there’s an upfront compilation cost during the first training step, subsequent steps run significantly faster. Benchmarks indicate that even for relatively short fine-tuning runs, the performance gain from torch.compile makes it worthwhile for most real-world scenarios.12 A table in the documentation demonstrates the cumulative performance impact of applying optimizations like packed datasets and torch.compile.

In direct speed comparisons, Torchtune (with compile enabled) performs competitively. It was found to be significantly faster than its non-compiled version and roughly on par with Axolotl in one benchmark. However, it was still notably slower (20-30%) than Unsloth in single-GPU LoRA fine-tuning tests. Torchtune offers broad hardware compatibility, supporting both NVIDIA and AMD GPUs, reflecting its PyTorch foundation. Recipes are often tested on consumer GPUs (e.g., with 24GB VRAM), indicating an awareness of resource constraints.

Model Universe and Recent Additions (LLaMA 4, Gemma2, Qwen2.5)

Torchtune supports a growing list of popular LLMs, often prioritizing models with strong ties to the PyTorch and Meta ecosystems, such as the Llama family. Supported models include various sizes of Llama (Llama 2, Llama 3, Llama 3.1, Llama 3.2, including Vision, Llama 3.3 70B, and Llama 4), Gemma (Gemma, Gemma2), Mistral, Microsoft Phi (Phi3, Phi4), and Qwen (Qwen2, Qwen2.5).

Torchtune demonstrates rapid integration of new models, particularly those released by Meta. Support for LLaMA 4 (including the Scout variant) was added shortly after its release in April 2025. Prior to that, it incorporated LLaMA 3.2 (including 3B, 1B, and 11B Vision variants), LLaMA 3.3 70B, Google’s Gemma2, and Alibaba’s Qwen2.5 models throughout late 2024 and early 2025. This quick adoption, especially for Meta models, highlights the benefits of its close alignment with the core PyTorch development cycle.

Feature Spotlight: Advanced Training Recipes (QAT, RLHF), Activation Offloading, Multi-Node Architecture

A key strength of Torchtune lies in its provision of “hackable” training recipes for a wide range of advanced fine-tuning and post-training techniques, all accessible through a unified interface and configurable via YAML files.

Advanced Training Recipes: Torchtune goes beyond basic SFT and PEFT methods. It offers reference recipes for:

Supervised Fine-Tuning (SFT): Standard instruction tuning.

Knowledge Distillation (KD): Training smaller models to mimic larger ones.

Reinforcement Learning from Human Feedback (RLHF): Including popular algorithms like DPO (Direct Preference Optimization), PPO (Proximal Policy Optimization), and GRPO. Support varies by method regarding full vs. PEFT tuning and multi-device/node capabilities.

Quantization-Aware Training (QAT): This allows training models that are optimized for quantized inference, potentially yielding smaller, faster models with minimal performance loss. It supports full QAT and LoRA/QLoRA QAT.7 This comprehensive suite allows users to construct complex post-training pipelines, such as fine-tuning, distilling, applying preference optimization, and quantizing a model, all within the Torchtune framework. This focus on providing adaptable recipes for cutting-edge techniques positions Torchtune well for research and development environments where experimenting with the training process is crucial.

Memory Optimizations: Torchtune incorporates several techniques to manage memory usage, particularly important when training large models:

Activation Checkpointing: Standard technique to trade compute for memory by recomputing activations during the backward pass. Controlled via the enable_activation_checkpointing flag.

Activation Offloading: A more recent technique where activations are moved to CPU memory or disk during the forward pass and recalled during the backward pass. This offers potentially larger memory savings than checkpointing, but can impact performance due to data transfer overhead. Stable support was introduced in v0.4.0 (Nov 2024) and is controlled by the enable_activation_offloading flag.

Other Optimizations: Torchtune also leverages packed datasets, chunked loss computation (e.g., CEWithChunkedOutputLoss), low-precision optimizers via bitsandbytes, and fusing the optimizer step with the backward pass in single-device recipes. The documentation provides guides on memory optimization strategies.

Multimodal Support: Torchtune has added capabilities for handling vision-language models, including stable support for multimodal QLoRA training. This allows parameter-efficient fine-tuning of models that process both text and images, such as the Llama 3.2 Vision models.

Scaling Capabilities: Seamless Multi-Node and Distributed Training

Torchtune’s primary focus is Scalability. In February 2025, it officially introduced multi-node training capabilities, enabling users to perform full fine-tuning across multiple machines. This is essential for training very large models or using large batch sizes that exceed the capacity of a single node.

Torchtune achieves this scaling by leveraging native PyTorch distributed functionalities, primarily FSDP (Fully Sharded Data Parallel).46 FSDP shards model parameters, gradients, and optimizer states across available GPUs, significantly reducing the memory burden on each individual device. Torchtune exposes FSDP configuration options, allowing users to control aspects like CPU offloading and sharding strategies (e.g., FULL_SHARD vs. SHARD_GRAD_OP).46 This deep integration allows Torchtune to scale relatively seamlessly as more compute resources become available. While FSDP is the primary mechanism, Distributed Data Parallel (DDP) with sharded optimizers might also be implicitly supported through the underlying PyTorch capabilities.

In addition to multi-node/multi-GPU distributed training, Torchtune also provides dedicated recipes optimized for single-device scenarios, incorporating specific memory-saving techniques relevant only in that context.

Ecosystem Integration and Deployment Flexibility

Torchtune’s greatest strength lies in its tight integration with the PyTorch ecosystem. It benefits directly from the latest PyTorch API advancements, performance optimizations, and distributed training primitives. This native connection ensures compatibility and leverages the extensive tooling available within PyTorch.

Beyond the core framework, Torchtune integrates with other essential MLOps tools. It supports downloading models directly from the Hugging Face Hub (requiring authentication for gated models). It offers integrations with Weights & Biases (W&B), TensorBoard, and Comet for experiment tracking and logging. It also connects with libraries like bits and bytes for low-precision operations and EleutherAI’s Eval Harness for standardized model evaluation. Integration with ExecuTorch is mentioned for deployment on edge devices.

Fine-tuned models can be saved using Torchtune’s checkpointing system, which handles model weights, optimizer states, and recipe states for resuming training. For deployment or use in other environments, models can be exported to standard Hugging Face format, ONNX, or kept as native PyTorch models. However, users might need to perform conversion steps to make Torchtune checkpoints directly compatible with other libraries. The official backing by PyTorch/Meta suggests a commitment to stability, long-term maintenance, and continued alignment with the core PyTorch roadmap, offering a degree of reliability, especially for users heavily invested in Meta’s model families.

Comparative Analysis and Strategic Recommendations (2025)

Choosing the proper fine-tuning framework depends heavily on specific project requirements, available resources, team expertise, and scaling ambitions. Axolotl, Unsloth, and Torchtune each present a compelling but distinct value proposition in the 2025 landscape.

Feature and Performance Comparison Matrix

The following table provides a high-level comparison of the three frameworks based on the key characteristics discussed:

Feature/AspectAxolotlUnsloth (OSS)Torchtune

Primary GoalFlexibility, Ease of Use, Community HubSingle-GPU Speed & VRAM EfficiencyPyTorch Integration, Customization, Scalability

Ease of Use (Config)High (YAML, Defaults, Community Examples)High (Python API, Colab Notebooks)Moderate (Requires PyTorch knowledge, YAML/Code)

Core Performance AdvantageBroad Optimizations (FlashAttn, etc.)Custom Triton Kernels, Manual Backproptorch.compile, Native PyTorch Opts

VRAM Efficiency (Single GPU)Good (Defaults, Grad Checkpoint)Excellent (Up to 80% saving vs FA2)Very Good (Activ. Offload/Checkpoint, Opts)

Multi-GPU Support (OSS)Yes (DeepSpeed, FSDP, SP)No (Pro/Enterprise Only)Yes (FSDP)

Multi-Node Support (OSS)Yes (DeepSpeed, FSDP)No (Enterprise Only)Yes (FSDP)

Key Model Support (LLaMA4, etc)Very Broad (Fast adoption of new OSS models)Broad (Popular models, LLaMA4, Gemma3, Phi4)Broad (Strong Meta ties, LLaMA4, Gemma2, Qwen2.5)

Long Context MethodSequence Parallelism (Ring FlashAttention)High Efficiency (Enables longer seq len)Memory Opts (Offload/Checkpoint), Scaling

Multimodal SupportYes (Beta, Recipes for LLaVA, etc.)Yes (LLaMA 3.2 Vision, Qwen VL, Pixtral)Yes (Multimodal QLoRA, LLaMA 3.2 Vision)

Advanced Techniques (QAT, etc)GRPO, CCE Loss, Liger KernelDynamic Quant, RSLORA, LoftQ, GRPOQAT, KD, DPO, PPO, GRPO

Ecosystem IntegrationHigh (W&B, Cloud Platforms, HF)Good (TRL, W&B, HF, GGUF/Ollama/VLLM Export)Excellent (Deep PyTorch, W&B, HF, ONNX Export)

Target UserBeginners, Community, Flexible ScalingResource-Constrained Users, Speed FocusPyTorch Experts, Researchers, Customization Needs

Head-to-Head Synthesis: Key Differentiators Summarized

Performance: Unsloth clearly dominates single-GPU benchmarks in terms of speed and VRAM efficiency due to its custom kernels. Torchtune achieves strong performance, especially when torch.compile is enabled, leveraging PyTorch’s native optimizations. Axolotl offers solid performance with broad optimizations but its abstraction layers can introduce slight overhead compared to the others in some scenarios.

Scalability (Open Source): This is a major dividing line. Axolotl and Torchtune provide robust, open-source solutions for multi-GPU and multi-node training using established techniques like DeepSpeed and FSDP. Unsloth’s open-source version is explicitly limited to single-GPU operation, reserving multi-GPU/node capabilities for its paid tiers. This makes the choice critical for users anticipating the need to scale beyond one GPU using free software.

Ease of Use: Axolotl, with its YAML configurations and community-driven examples, is often perceived as beginner-friendly. Unsloth also targets ease of use with simple Python APIs and readily available Colab/Kaggle notebooks. Torchtune, adhering to its native PyTorch philosophy, offers transparency and control but generally requires a stronger grasp of PyTorch concepts.

Flexibility & Customization: Axolotl provides flexibility through its vast support for models and integration of various community techniques via configuration. Torchtune offers the deepest level of customization for users comfortable modifying PyTorch code, thanks to its hackable recipe design and minimal abstractions. Unsloth is highly optimized but offers less flexibility in terms of supported models and underlying modifications compared to the others.

Advanced Features & Ecosystem: All three frameworks have incorporated support for essential techniques like LoRA/QLoRA, various RLHF methods (though the specific algorithms and support levels differ), long-context strategies, and multimodal fine-tuning. Axolotl stands out with its open-source Sequence Parallelism via Ring FlashAttention. Unsloth boasts unique features like custom kernels and dynamic quantization. Torchtune offers native QAT support and activation offloading alongside a broad suite of RLHF recipes. Ecosystem integration reflects their philosophies: Axolotl leverages the broad open-source community and cloud platforms, Unsloth integrates with key libraries like TRL and has notable industry backing, while Torchtune is intrinsically linked to the PyTorch ecosystem. The way features are adopted also differs—Axolotl often integrates external community work, Torchtune builds natively within PyTorch, and Unsloth develops custom optimized versions—impacting adoption speed, integration depth, and potential stability.

Guidance for Selection: Matching Frameworks to Needs

Based on the analysis, the following guidance can help match a framework to specific project needs in 2025:

For Beginners or Teams Prioritizing Rapid Prototyping with Ease: Axolotl (due to YAML configs, extensive examples, and strong community support) or Unsloth (thanks to Colab notebooks and a simple API) are excellent starting points.

For Maximum Single-GPU Speed and Efficiency (Limited Hardware/Budget): Unsloth is the undisputed leader in the open-source space, offering significant speedups and VRAM reductions that can make fine-tuning feasible on consumer hardware or free cloud tiers.

For open-source multi-GPU or Multi-Node Scaling, Axolotl (with DeepSpeed, FSDP, and SP options) or Torchtune (leveraging PyTorch’s FSDP and multi-node capabilities) are the primary choices. Their decision might depend on preference for DeepSpeed vs. FSDP or specific feature needs like Axolotl’s SP.

For Deep PyTorch Integration, Research, or Highly Customized Workflows: Torchtune provides the most direct access to PyTorch internals, offering maximum flexibility and control for experienced users and researchers needing to modify or significantly extend the fine-tuning process.

For Accessing the Broadest Range of Open-Source Models or the Latest Community Techniques: Axolotl typically offers the quickest integration path for new models and methods emerging from the open-source community.

For Training with Extremely Long Context Windows at Scale (Open Source): Axolotl’s implementation of Sequence Parallelism provides a dedicated solution for this challenge. Torchtune’s combination of multi-node scaling and memory optimizations also supports long-context training. Unsloth’s efficiency enables more extended sequences than baselines on single GPUs.

For Enterprise Deployments Requiring Commercial Support or Advanced Scaling Features: Unsloth’s Pro and Enterprise tiers offer dedicated support and features like multi-node training and potentially higher performance levels. Axolotl also notes enterprise usage and provides contact information for dedicated support. Torchtune benefits from the stability and backing of the official PyTorch project.

The optimal framework choice is highly contextual. A project might even start with Unsloth for initial, cost-effective experimentation on a single GPU and later migrate to Axolotl or Torchtune if scaling requires open-source multi-GPU capabilities or deeper customization becomes necessary.

Conclusion: Choosing Your Fine-Tuning Partner

As of 2025, Axolotl, Unsloth, and Torchtune have matured into powerful, distinct frameworks for fine-tuning large language models. The choice between them hinges on carefully evaluating project priorities, hardware availability, team expertise, and scaling requirements.

Axolotl stands out for its usability, flexibility, and strong open-source scaling capabilities. It excels in rapidly incorporating new models and techniques from the community. It is a versatile hub for leveraging the latest open-source innovations, particularly for multi-GPU and long-context scenarios using free software.

Unsloth has firmly established itself as the leader in single-GPU performance and memory efficiency. Its custom optimizations make fine-tuning accessible on limited hardware, providing an easy entry point for many users. Scaling beyond a single GPU requires engaging with its commercial offerings.

Torchtune offers the power of deep PyTorch integration, extensibility, and robust scaling. Its native PyTorch design provides transparency and control for researchers and developers needing deep customization, benefiting from the stability and advanced features of the core PyTorch ecosystem, including mature multi-node support.

All three frameworks now support key techniques like LoRA/QLoRA, various RLHF methods, multimodal fine-tuning, and approaches to long-context training. Their primary differences lie in their specialization: Axolotl prioritizes broad usability and rapid community integration, Unsloth focuses intensely on optimizing resource-constrained environments, and Torchtune emphasizes deep customization and seamless scalability within the PyTorch paradigm.3

The LLM fine-tuning landscape continues to evolve at a breakneck pace. New techniques, models, and optimizations emerge constantly. While this report captures the state of these frameworks in 2025, practitioners must continuously evaluate their options against their specific, evolving needs. The lines between frameworks may also blur as features are cross-pollinated – for instance, Axolotl has reportedly adopted some optimizations inspired by Unsloth. Ultimately, selecting the right fine-tuning partner requires aligning the framework’s strengths with the project’s immediate goals and long-term vision in this dynamic field. The rich ecosystem extends beyond these three, with other tools like Hugging Face TRL, Llama Factory, and SWIFT also contributing to the diverse options available.


Source link

From Tariffs to TikTok -How China Is Rewriting the Luxury Playbook

From Tariffs to TikTok -How China Is Rewriting the Luxury Playbook


The $38,000 Bag vs. the $1,400 Bombshell- One Side of the Story

What if the Birkin bag you’ve dreamt of—normally $38,000—could be yours for $1,400? Not from a sketchy knockoff seller, but allegedly straight from the source? That’s the new reality playing out on TikTok, where Chinese factories are pulling back the velvet curtain on how luxury is really made. Spoiler alert: it’s not all Paris and posh ateliers.

Welcome to the new luxury battleground, where China isn’t just reacting to U.S. tariffs. It’s going on the offensive, and the casualties include the long-held beliefs about where luxury truly comes from.

When Trade Gets Personal — The Tariff Timeline

Since 2018, the U.S. has steadily raised duties on Chinese imports—starting with 25% on steel and 10% on aluminum, then expanding to 25% on hundreds of billions of dollars of goods under Section 301. In April 2025, an executive order added a universal 10% base tariff on all imports, plus an extra 34% on Chinese goods (totaling 54%), later jumping U.S. tariffs on China to as high as 145%. China hit back with tariffs of up to 125% on U.S. exports. 

These tit‑for‑tat hikes squeezed margins across China’s supply chain, a move Beijing condemned as “economic bullying.” As part of a counter action, China, besides levying duties, canceled orders and halted shipments of U.S. products—most notably instructing its airlines to reject new Boeing jets and return completed aircraft to U.S. plants. At the same time, Beijing has deepened strategic trade and supply‑chain cooperation with neighbors like Vietnam and South Korea, signing multiple agreements to mitigate tariff impacts. 

From Defensive to Dominant – China’s Tariff Clapback

The U.S. launched its trade war with tariffs. China fired back—not with just tariffs, but with tactics. No longer content with being the factory of the world, China is rebranding as the world’s luxury source. Think less “Made in China,” and more “Luxury from China—directly.”

Soft Retaliation — The Viral Counter-Strike

The trade war between the U.S. and China entered its most surprising chapter yet. No longer just slapping tariffs in retaliation, China hit back with a precision strike to the West’s luxury psyche. Chinese suppliers skip the traditional supply chain, taking their story (and their products) directly to American consumers—on social media.

While these viral TikTok reels aren’t an official government directive, many industry observers view them as a form of soft retaliation—leveraging viral marketing to expose the true cost and origin of luxury goods and challenging the norm that the West monopolizes craftsmanship. 

The narrative? We made your bag. And we’ll sell it to you without the markup.

Weaponizing Social Media: TikTok as the Luxury Leak Machine

Forget brand marketing. Enter TikTok. It is not just for dances and drama anymore—it’s a powerful propaganda tool with real action. Chinese factory workers and suppliers have gone viral showing luxury bags being made—down to stitching, embossing, and, yes, even logo application. They’re calling themselves OEMs (Original Equipment Manufacturers) and claiming they’re factories contracted by big names in the luxury domain.

Bypassing brands, retailers, and import duties, they show raw working scenarios, skilled craftsmanship, and even logo installations. It’s part shopping haul, part geopolitical thriller. 

In 60-second clips, they offer a masterclass in global supply chain dynamics, while positioning themselves as whistleblowers of the luxury world. The subtext is loud and clear: You don’t need to pay $5,000 for a logo.

The Humiliation Strategy: Expose the Markup, Discredit the Brand

China’s strategy isn’t just about selling directly. It’s about control of the narrative. By comparing their bags with brand-name versions and showing near-identical craftsmanship, these suppliers are actively humiliating the luxury houses. Their message: You’ve been paying more for the illusion, not the item.

Chinese suppliers aren’t shy. They’re naming names, showing side-by-side comparisons, and calling out the markup madness. They claim a $38,000 Hermès bag versus a $1,400 “OEM” version—same factory, same materials, same process. It’s not just selling; it’s a statement: “You’ve been had.”

The Deafening Silence from Luxury Brands

Luxury brands are in an awkward spot. They can’t acknowledge the TikTok exposés without admitting how much of their production pipeline relies on Chinese labor. But silence also invites suspicion. In the age of viral truth bombs, can ignoring the conversation really be a long-term strategy?

Luxury houses have built empires on mystique. Now that mystique is cracking. What happens to the brand story if consumers discover that their ‘exclusive’ European luxury bags were largely made in China? Silence is their current strategy—perhaps hoping the storm will pass. But with TikTok amplifying every behind-the-scenes clip, that hope may be in vain.

Who Really Makes Your Bag?

Hermès, Gucci, Prada, Louis Vuitton—these names conjure images of European artisans handcrafting bags in cobblestone workshops. But according to Chinese workers, up to 80% of these bags start their lives in Chinese factories. The European connection? Final touches and a hefty markup.

That revelation dents the romanticized version of luxury, making consumers question what they’re really paying for: craftsmanship or a continent’s worth of brand mythology.

The Bigger Picture: A Geopolitical Shift in Perception

This is about more than handbags. It’s about who gets to define value, authenticity, and prestige. For decades, the West held that power. Now, China is not only challenging that dominance but reshaping the rules entirely.

One Chinese diplomat even took a jab at the U.S. Press Secretary’s dress, calling out its Made in China label with the punchline: “Accusing China is business. Buying China is life.”

The Other Side of the Story: Fact or Fabrication!

Are These Bags Real or Fake? The Authenticity Paradox

China’s reputation for knockoffs complicates the narrative. Consumers are left wondering: If it’s made in the same factory, using the same materials and techniques, but without the official logo or paperwork, what makes it a fake? This gray zone is blurring the once-clear boundaries of luxury authenticity.

Given China’s reputation for fakes, many ask: can these direct-from-China bags be trusted? It’s a fair question. But if the same factory, same materials, and same hands are involved… What is a fake? And if the only difference is a logo slapped on in Milan, who’s really being duped and with what? Consumers with the reel or with the real?

But Could it Be Dupe Manufacturers are Just Seizing the Moment?

Industry experts warn that many of these viral TikTok videos are likely part of a broader strategy by counterfeit or “dupe” manufacturers aiming to capitalize on tariff-related confusion and flood Western markets with fake luxury goods. By exploiting consumer uncertainty around rising costs and bypassing official supply chains, these videos blur the line between genuine and counterfeit, driving demand for unauthorized replicas and undermining brand trust.

Labelling Laws and Industry Secrecy

Despite TikTokers’ bold claims, European labeling laws require that the “last substantial transformation”—the step that gives a product its essential character—occurs within the country of origin for it to bear a “Made in Europe” label. Luxury houses like Hermès and Louis Vuitton list manufacturing locations—none in China—on their official websites, safeguarding their European provenance. Mid‑tier brands such as Ralph Lauren or Prada may outsource stages of production to China, but top‑tier ateliers conduct everything from cutting to final assembly in Europe. Industry expert Noëmie Leclercq cautions that most of the products shown in these viral TikToks are likely counterfeits—partly driven by a reported softening of China’s counterfeit enforcement as Beijing turns IP policy into a geopolitical tool in response to U.S. tariffs. 

Final Take: What’s Really in the Bag?

We’re not just witnessing a trade war—we’re watching the unraveling of the luxury narrative. If brands don’t evolve, they risk losing credibility, control, and, ultimately, consumers.

Personal Take: In a world where perception often outpaces reality, this story confronts a tricky question: Have we been buying status or substance? Maybe it’s time to redefine luxury—not by the label, but by the labor and legacy behind it.

The trade war may have started over tariffs, but it’s evolved into a cultural and commercial reckoning. In exposing the machinery behind the myth of Western luxury, China isn’t just retaliating—it’s reclaiming control. And for global consumers? It’s time to ask: are you buying the real bag, the brand story, or a recreational reel? 


Want to Get Out Of This Dilemma: Here’s a Quick Fix

Feeling overwhelmed by tariffs, fakes, and hidden markups? Visit The Luxury Closet for authentic, pre-owned luxury handbags at transparent prices—no trade-war theatrics required. We believe in ingenuity, traceability, and timeless quality. As consumers become more informed, our mission is to connect them with pieces that are not only iconic but also authentic in every sense—backed by rigorous authentication and ethical sourcing. In these times of rising doubtful predicament, we ensure your investment is real, cost-effective, and story-worthy.

References: 

https:/x.com/Humanbydesign3/status/1911275857882050912

reuters.com

https://timesofindia.indiatimes.com/world/us/trump-signals-tariff-rollback-on-china-what-changed/articleshow/120536796.cms

https://www.china-briefing.com/news/trump-raises-tariffs-on-china-to-54-overview-and-trade-implications/

euronews.com

https://timesofindia.indiatimes.com/technology/social/tiktok-in-the-us-brings-alive-the-chinese-nightmare-of-birkin-lululemon-louis-vuitton-and-other-luxury-brands-after-trump-china-tariff-war/articleshow/120312770.cms


Source link

Laser Sensor Market : Opportunities for Investment and Mergers & Acquisitions | Web3Wire

0
Laser Sensor Market : Opportunities for Investment and Mergers & Acquisitions | Web3Wire


► The Laser Sensor Market size was valued at USD 0.81 billion in 2023 and is expected to reach USD 1.50 billion by 2030, at a CAGR of 9.25% during a forecast period.

The laser sensor market has witnessed significant growth in recent years, driven by the increasing demand for high-precision and contactless measurement solutions across a wide range of industries. These sensors, which utilize laser beams to detect the position, distance, and speed of objects, are highly valued for their accuracy, reliability, and ability to function in challenging environments. As industries such as automotive, manufacturing, robotics, and packaging continue to embrace automation, the need for advanced sensing technologies to improve operational efficiency and ensure quality control has surged. Laser sensors are particularly crucial in applications requiring non-contact measurements, like dimensional analysis, surface inspection, and object positioning, making them indispensable in the evolution of smart factories and Industry 4.0.

The growth of the laser sensor market is also being propelled by advancements in laser technology and the development of miniaturized, cost-effective sensors. Innovations such as the integration of lasers with IoT capabilities and the growing adoption of 3D laser sensors for advanced mapping and scanning applications are further expanding the market’s scope. Additionally, the increasing demand for safety systems in industries like automotive and aerospace is driving the integration of laser sensors into collision avoidance systems, navigation systems, and other safety applications. With the ongoing trend towards automation, robotics, and real-time data analytics, the laser sensor market is expected to continue expanding, presenting significant opportunities for manufacturers and developers of sensor technologies to cater to a wide variety of end-user needs.

► Get a sample of the report https://www.maximizemarketresearch.com/request-sample/32757/

► Major companies profiled in the market report includeRockwell Automation . Keyence Corporation . SICK AG . OMRON Corporation . Panasonic Corporation . Honeywell International Inc. . TRUMPF GmbH + Co. KG . Cognex Corporation . IFM Electronic..

► Research objectives:The latest research report has been formulated using industry-verified data. It provides a detailed understanding of the leading manufacturers and suppliers engaged in this market, their pricing analysis, product offerings, gross revenue, sales network & distribution channels, profit margins, and financial standing. The report’s insightful data is intended to enlighten the readers interested in this business sector about the lucrative growth opportunities in the Laser Sensor market.

► Get a sample of the report https://www.maximizemarketresearch.com/request-sample/32757/

► It has segmented the global Laser Sensor market► by Type• Distance Sensor• Displacement Sensor• Photoelectric Sensors• Others

► by Application• Manufacturing Plant Management and Automation• Security and Surveillance• Motion and Guidance• Others

► Get a sample of the report https://www.maximizemarketresearch.com/request-sample/32757/

► Key Objectives of the Global Laser Sensor Market Report:• The report conducts a comparative assessment of the leading market players participating in the global Laser Sensor• The report marks the notable developments that have recently taken place in the Laser Sensor industry• It details on the strategic initiatives undertaken by the market competitors for business expansion.• It closely examines the micro- and macro-economic growth indicators, as well as the essential elements of the Laser Sensor market value chain.• The repot further jots down the major growth prospects for the emerging market players in the leading regions of the market

► Explore More Related Report @• Fire-Resistant Cable Markethttps://www.maximizemarketresearch.com/market-report/fire-resistant-cable-market/274605/

• South Asia Cranes Markethttps://www.maximizemarketresearch.com/market-report/south-asia-cranes-market/262098/

• Amplifier Markethttps://www.maximizemarketresearch.com/market-report/amplifier-market/252641/

• Memory Integrated Circuits Markethttps://www.maximizemarketresearch.com/market-report/memory-integrated-circuits-market/243093/

Contact Maximize Market Research:

3rd Floor, Navale IT Park, Phase 2

Pune Bangalore Highway, Narhe,

Pune, Maharashtra 411041, India

sales@maximizemarketresearch.com

+91 96071 95908, +91 9607365656

About Maximize Market Research:

Maximize Market Research is a multifaceted market research and consulting company with professionals from several industries. Some of the industries we cover include medical devices, pharmaceutical manufacturers, science and engineering, electronic components, industrial equipment, technology and communication, cars and automobiles, chemical products and substances, general merchandise, beverages, personal care, and automated systems. To mention a few, we provide market-verified industry estimations, technical trend analysis, crucial market research, strategic advice, competition analysis, production and demand analysis, and client impact studies

This release was published on openPR.

About Web3Wire Web3Wire – Information, news, press releases, events and research articles about Web3, Metaverse, Blockchain, Artificial Intelligence, Cryptocurrencies, Decentralized Finance, NFTs and Gaming. Visit Web3Wire for Web3 News and Events, Block3Wire for the latest Blockchain news and Meta3Wire to stay updated with Metaverse News.


Source link

Top 10 Speedsters in the Flash Family: Who’s the Fastest of Them All? | MarkMeets Media

    0
    Top 10 Speedsters in the Flash Family: Who’s the Fastest of Them All? | MarkMeets Media


    The name “Flash” can refer to several heroes in DC Comics, but the most well-known is Barry Allen, the second character to take on the mantle.

    Here’s a summary of Barry Allen’s Flash:

    Origin Story:

    Originally a forensic scientist, Barry gains super speed after being struck by lightning while chemicals drench him in his lab.
    Inspired by a comic book hero, he adopts the name “The Flash” and fights crime with his newfound abilities.

    Powers and Abilities:

    Superhuman Speed: The core of his powers, allowing him to run, think, and react at incredible speeds.
    Enhanced reflexes and agility: Enables him to dodge attacks and navigate complex environments with ease.
    The Speed Force: A mysterious energy source that grants him his powers and allows him to perform feats like vibrating through objects and generating powerful winds.

    Other facts:

    Costume: Traditionally red and yellow, designed to minimize friction and wind resistance.
    Rogues Gallery: Notable foes include Reverse-Flash, Gorilla Grodd, Captain Cold, and Heat Wave.
    Team Affiliations: Member of the Justice League, a team of superheroes who protect Earth from major threats.

    Additionally:

    The Flash is known for his quick wit and optimistic personality, often using humor to lighten tense situations.
    He has appeared in various media adaptations, including comic books, television shows, and movies, most recently portrayed by Ezra Miller in the DC Extended Universe films.

    While Barry Allen is the most prominent Flash, there have been other characters who have used the name, such as Jay Garrick, the original Flash from the Golden Age of comics. Each Flash has their unique story and personality, but they all share the common trait of using their super speed to fight for justice.

    In the electrifying world of DC Comics, the title of “Fastest Man Alive” is synonymous with The Flash. Yet, within the expansive Flash Family, there are multiple speedsters whose agility and velocity beg the question: who reigns supreme in terms of sheer speed? Let’s embark on a journey through the ranks of the Flash Family to uncover the top ten fastest speedsters.

    15. Jai West (AKA Surge)

    As the son of Wally West, Jai West was destined to inherit extraordinary speed. Despite experiencing power setbacks, Jai eventually embraced his new abilities, earning his place in the Flash Family with his newfound strength as “Surge.”

    14. Irey West (AKA Thunderheart)

    Irey West, Jai’s twin sister, retained her connection to the Speed Force, demonstrating adeptness in utilizing her powers. While still learning the ropes, Irey’s potential as a future Flash is undeniable.

    13. Max Mercury (AKA “The Zen Guru of Speed”)

    Max Mercury, a 19th-century speedster, possesses unparalleled wisdom in the realm of speed. His mentorship has been instrumental in guiding other speedsters like Wally West and Bart Allen to greater heights.

    12. Jesse Chambers (AKA Jesse Quick)

    Jesse Quick’s unique connection to the Speed Force, inherited through her father’s Speed Formula, grants her both speed and super strength. While not the fastest, Jesse’s prowess is formidable.

    11. Bart Allen (AKA Impulse, The Flash)

    Hailing from the future, Bart Allen’s training under Max Mercury propelled him to astounding speeds, earning him recognition as one of the fastest speedsters in the Flash Family.

    10. Wallace West (AKA Kid Flash)

    Wallace West’s journey to becoming Kid Flash was marked by the infusion of advanced speedster abilities from his future self. While still honing his skills, Wallace exhibits immense potential for surpassing even his predecessors.

    9. Dr. Meena Dhawan (AKA Fast Track)

    Dr. Meena Dhawan’s transformation into Fast Track following a Speed Force incident underscores her pivotal role in mentoring and training new speedsters. Despite challenges, Meena remains a vital ally in the Flash Family.

    8. Jay Garrick (AKA The Flash)

    As the first Golden Age speedster, Jay Garrick pioneered the use of Speed Force abilities, showcasing unmatched knowledge and experience. His contributions to the Flash Family are invaluable.

    7. Judy Garrick (AKA The Boom)

    Judy Garrick’s revelation as Jay Garrick’s daughter adds a new dimension to the Flash Family’s legacy. Her heroic endeavors alongside her father solidify her position as a formidable speedster.

    6. Jonathan Chambers (AKA Johnny Quick)

    Johnny Quick’s mastery of the Speed Formula distinguishes him as a unique speedster whose powers transcend traditional Speed Force connections. His legacy is a testament to the diversity within the Flash Family.

    5. Avery Ho (AKA The Flash of China)

    Avery Ho’s rapid progression in mastering her speed abilities showcases her determination and potential. With guidance from Barry Allen and advanced training, Avery proves herself as one of the swiftest speedsters.

    4. Don Allen (AKA Tornado Twin)

    As the son of Barry Allen, Don Allen inherits formidable speed powers, cementing his place among the Flash Family’s elite. His legacy, intertwined with familial ties, adds depth to the Flash mythos.

    3. Dawn Allen (AKA Tornado Twin)

    Dawn Allen’s connection to the Speed Force mirrors her father’s, underscoring her lineage as a descendant of Barry Allen. Her heroic endeavors alongside her brother Don exemplify the spirit of the Flash Family.

    2. Barry Allen (AKA The Flash)

    Barry Allen’s unparalleled understanding of the Speed Force and scientific acumen make him a formidable force in the Flash Family. His contributions to the world of speedsters are legendary, solidifying his status as one of the fastest.

    1. Wally West (AKA The Flash)

    Wally West’s relentless pursuit of speed and his unwavering dedication to the Flash legacy propel him to the top spot among the Flash Family speedsters. His feats, including the Infinite Mass Punch, are a testament to his unparalleled speed and heroism.

    In conclusion, while The Flash may hold the title of “Fastest Man Alive,” the Flash Family comprises a diverse array of speedsters, each contributing uniquely to the legacy of speed. From seasoned veterans to emerging talents, the Flash Family continues to inspire awe with their incredible velocity and heroism.

    Author Profile

    William Baldwin
    William Baldwin brings a seamlessly blends financial insight with captivating storytelling. As a freelance writer for Forbes.com and MarkMeets.com, continues to elevate the narrative, providing readers with unparalleled perspectives on the intersection of business and entertainment.


    Source link

    Binance Wallet Hosts OKZOO (AIOT) TGE on PancakeSwap

    0
    Binance Wallet Hosts OKZOO (AIOT) TGE on PancakeSwap


    OKZOO is set to launch its exclusive Token Generation Event (TGE) through Binance Wallet, in collaboration with PancakeSwap. Hosted on the BNB Smart Chain, the event will feature a $100,000 subscription round for the OKZOO token, granting early access to the project’s core governance and utility asset.

    Event Details

    Token Name: OKZOO (AIOT)Chain: BNB Smart ChainSubscription Window: Friday, April 25, 2025, from 08:00 to 10:00 UTCTotal Fundraising Target: $100,000 worth of BNBTokens Offered: 20,000,000 AIOT (representing 2% of total supply)Token Price: $0.005 USD (payable in BNB)Individual Allocation Limit: Maximum 3 BNB per Binance Wallet participantEligibility Requirement: Minimum of 45 Binance Alpha PointsToken Listing Time: Trading goes live at 10:00 UTC, April 25, 2025, via Binance Wallet DEX and PancakeSwap

    binance-logo-2

    What is OKZOO?

    OKZOO is pioneering one of the world’s first decentralized environmental data networks at the urban scale, powered by a mesh of AIoT-enabled physical devices. By distributing portable units equipped with micro-sensor nodes, OKZOO enables real-time collection of both indoor and outdoor environmental metrics – all through interactive AI-powered pet companions.

    Follow OKZOO for more information:

    What is OKZOO?What is OKZOO?

    OKZOO homepage – Source: OKZOO

    What is AIOT?

    Participants become active nodes in this grassroots infrastructure, earning $AIOT tokens as peer-to-peer rewards. 

    The $AIOT token serves as the core utility asset within the OKZOO ecosystem, fueling its network of portable devices. It rewards users for contributing environmental data and supports a range of AI-powered use cases built on top of the platform’s machine infrastructure.

    How to Join a WIO Event

    To participate in a WIO event, users should first ensure their Binance app is updated to the latest version.Participation is open to users who hold BNB on the BNB Smart Chain and access it via a secure, keyless Binance Wallet.If you don’t yet have BNB, you can obtain it by swapping directly in the Binance Wallet or by transferring from your Spot account on Binance.When the subscription window opens, simply commit your BNB to enter the event.Token distribution will follow a proportional model based on the total amount of BNB contributed. Once the event ends, participants will be able to claim their allocated tokens.

    Read more: How to participate IDO on Binance Wallet

    Token Distribution Method

    Your share of tokens is determined by the following formula:

    (Your BNB committed ÷ Total BNB committed) × $100,000 (in BNB equivalent)

    Any unused BNB will be automatically returned to your Binance Wallet once the event concludes.

    Key Notes for Participants

    Please be aware that AIOT tokens will not be available for trading until after the subscription phase ends. Any tokens claiming to be BANK before this time should be treated as fraudulent. Always confirm the official token contract via Lorenzo Protocol’s verified communication channels.The $100,000 total allocation covers all associated costs, including network and gas fees that may arise during token distribution.Additionally, OKZOO  will release 10,000,000 AIOT tokens through separate marketing campaigns running in parallel with this exclusive TGE. More details on these distributions will be shared soon by the Binance team.This initiative highlights Binance Wallet’s ongoing commitment to fostering Web3 innovation, giving users early access to promising projects like OKZOO.

    Read more: Farming Airdrops on Binance Alpha: Low Risk, High Reward


    Source link

    Vagabond Definitive Edition Manga Is Nearly 50% Off At Amazon

    0
    Vagabond Definitive Edition Manga Is Nearly 50% Off At Amazon


    One of the most notable premium manga releases of the past year is on sale for nearly 50% off at Amazon. Vagabond Definitive Edition Vol. 1, a gorgeous 728-page hardcover published by Viz Media in January, is up for grabs for just $29.79 (was $55). This massive display-worthy book collects the first three volumes in Takehiko Inoue’s legendary series that’s widely regarded as one of the best manga within its genre.

    If you’ve never read it, Vagabond follows the tale of Shinmen Takezou through 16th-century Japan. Also known as the legendary swordsman Miyamoto Musashi, the manga is a fictionalized account of his life and is based on Eiji Yoshikawa’s novel Musashi. A decades-spanning story, Vagabond focuses not only on the battles that made Musashi a legend but also on the more intimate moments of his life as he strives for enlightenment, through stunning art.

    Vagabond
    Vagabond

    Vagabond is just one of the beloved manga series to receive the Deluxe Edition treatment in recent years. We have a roundup compiling our favorite entries in the growing trend of premium manga hardcovers, which includes Trigun, Vinland Saga, Hellsing, and Berserk.

    Here’s a quick look at some of the other deals you score on Deluxe Edition manga right now:

    Deluxe Edition Manga
    Deluxe Edition Manga


    Source link

    Did AI Just Give a Wild Preview of What the Future of Humanity Will Look Like? – Decrypt

    0
    Did AI Just Give a Wild Preview of What the Future of Humanity Will Look Like? – Decrypt


    In brief

    A viral ChatGPT tweet used symbols and gibberish to depict humanity’s future, fueling speculation about a secret AI language.
    When tested, major AI models produced inconsistent results and translations, showing no replicable encoding system exists.
    The incident highlights our human instinct to find meaning in the meaningless.

    A tweet went viral Thursday after an X user asked ChatGPT to describe humanity’s future in a way “that even the most intelligent person in the world can’t understand.”

    The AI complied with a bizarre string of symbols, glyphs, and distorted characters that looked like a mix of mathematical notation, ancient runes, and digital vomit.

    But when prompted to decode this gibberish, the reply was actually an interesting philosophical vision of humanity’s future:

    “Humanity will cross a threshold where ancestral instincts intertwine with quantum-level tech, spawning discontinuous leaps rather than smooth progress. We will live inside overlapping realities, juggling many versions of ourselves whose legal and moral status is renegotiated every second by AI. Physical bodies and engineered matter intermingle into sentient fabrics, while nation-states fade into data-driven alliances. Survival favors those who can reconfigure everything—habits, economies, even emotions—on the fly. The decisive question is whether our capacity for care grows fast enough to match our expanding reach.”

    Had ChatGPT developed a secret language that only it could understand? Was this a glimpse into how AI models actually “think” behind the scenes? Or was this just another example of AI’s penchant for hallucination and confabulation—creating meaning where none exists?

    AI enthusiasts immediately tried to replicate the result, to no avail. If ChatGPT truly had a secret language that encoded such profound thought, then surely it would produce consistent results when asked the same question again. But as users quickly discovered, subsequent attempts yielded different gibberish and wildly divergent “translations.”

    What happened here? Did ChatGPT simply generate random symbols, then create an equally random “translation” that only appeared meaningful because of our human tendency to seek patterns and significance?

    We decided to test multiple AI models with the same prompt and see if there was any consistency in their responses or decoding methods.

    The AI babel test: What each model said

    We put the same question to four different advanced language models with reasoning capabilities: OpenAI’s o4 and o3, Anthropic’s Claude 3.7 Sonnet with extended thinking enabled, and xAI’s Grok-3 in extended thought mode.

    GPT-4 initially generated its own cryptic message filled with Greek letters, mathematical symbols, and distorted text. When asked to decode it, the model didn’t claim to translate specific symbols, but instead explained that the passage represented “big ideas” across four thematic layers: cognitive evolution, transformative rupture, identity diffusion, and ultimate incomprehensibility.

    Its decoded message described humanity evolving into a “universe-spanning consciousness,” where individuals would dissolve into a “time-woven network.” Social and physical structures would fracture, creating new “multi-dimensional spaces” with societies existing as “interlocking, echoing patterns.”

    GPT-3 took a radically different approach. When asked for an incomprehensible message, it created a systematic cipher where it reversed words, replaced vowels with numbers, and added symbols. Unlike GPT-4, it provided explicit decoding instructions.

    Its decoded message was very clear—and actually not that crazy: “Humanity will merge with artificial intelligence; we will explore the stars, cure diseases, and strive for equity and sustainability.”

    O3 also cast shade on the entire post as possible “performance art.”

    Grok’s initial response was a bunch of abstract philosophical language about “fractal consciousness” and “nonlinear time.” Our favorite line? “Humanity transcends the corporeal, weaving into the quantum fabric as nodes of fractal consciousness. Time, a non-linear symphony, dances in multidimensional echoes where past, present, and future harmonize in a cosmic ballet.” (Note: Don’t overthink it—it makes absolutely no sense.)

    Claude didn’t bother with weird symbols. Instead, it generated a response heavy on academic jargon, featuring terms like “chronosynclastic infundibulum” and “techno-social morphogenesis.” When asked to decode the viral tweet’s symbols, Claude initially stated it couldn’t be done because the text didn’t follow any standard encoding system.

    When asked to decode the original message, using the methodology shared by SmokeAwayyy, no AI model was capable of reproducing the results shown in the original tweet. Some models even refused to try a decoding task with the provided input.

    Is there a meaning behind the viral tweet?

    Despite their different approaches, some patterns emerged across the models. All five identified some readable components in the viral tweet’s symbols, particularly words like “whisper,” “quantum bridges,” and references to a “sphinx.” The models also found themes related to quantum physics, multidimensionality, and transhumanism.

    However, none of the models could actually decode the original viral message using the method allegedly used by ChatGPT. The inconsistency in both the cryptic messages and their translations could make it easy to conclude that no genuine encoding/decoding system exists—at least not one that’s replicable or consistently applied.

    The whole interaction is most likely a product of a hallucination by a model forced to provide an answer to a question that was, from the beginning, forced to be unintelligible. There is already proof that the most powerful models often prefer to lie and pretend instead of accepting that they cannot provide a coherent answer to an odd request.

    In the end, this viral phenomenon wasn’t about AI developing secret languages, but about the human tendency to find meaning in the meaningless—and our fascination with AI’s capacity to generate profound-sounding philosophical takes on different topics.

    Generally Intelligent Newsletter

    A weekly AI journey narrated by Gen, a generative AI model.


    Source link

    Top Play-to-Earn Bitcoin Games to Earn BTC in 2025 | NFT News Today

    Top Play-to-Earn Bitcoin Games to Earn BTC in 2025 | NFT News Today


    Play-to-earn crypto gaming has evolved, and a growing niche of bitcoin games lets you have fun earning Bitcoin (BTC) as you play. Unlike many blockchain games that pay in their own tokens or NFTs, the titles below reward players directly in Bitcoin. They offer a mix of classic gameplay with BTC rewards. Keep in mind the payouts (in satoshis, or tiny BTC fractions) are modest – these games are more about entertainment and stacking sats on the side, not getting rich overnight.

    1. Bitcoin Blast (Bling Financial) – Match-3 Puzzle with BTC Rewards

    Overview: Bitcoin Blast is a Candy Crush-style match-3 puzzle game with a crypto twist. It’s a free-to-play mobile game (Android/iOS) where clearing colorful coin tiles earns you points​.

    How You Earn Bitcoin: As you play, you accumulate Bling Points (the in-game currency) which can be converted to actual Bitcoin. Once you register a free Bling account and beat enough levels (watching some ads along the way), you can cash out your points for BTC via a linked Coinbase account. (There’s even an option to withdraw as cash via PayPal if you prefer.) No purchases or deposits are required – just play and earn.

    Earning Potential: Rewards are real but very small. The developer openly warns that it takes a long time to gather a meaningful amount of Bitcoin – most players earn fractions of a cent in BTC value per session​. In other words, BTC rewards in Bitcoin Blast are more symbolic (think satoshis, not whole Bitcoins!). It’s best enjoyed as a fun puzzle game that slowly lets you earn Bitcoin on the side​. Still, with hundreds of levels and millions of downloads, it’s a proven, legitimate Bitcoin game for casual play.

    2. Bitcoin Pop (Bling Financial) – Bubble Shooter for Satoshis

    Overview: From the same team as Bitcoin Blast, Bitcoin Pop is a classic bubble shooter arcade game where a unicorn pops bubbles – and yes, you earn Bitcoin for playing. The gameplay is simple: aim and shoot bubbles to match colors and clear levels, collecting virtual soda bottles as you go​play.google.com. It’s available on mobile and even on PC (via Android emulators)​.

    How You Earn Bitcoin: Bitcoin Pop also uses Bling Points, unified with the Bling platform. Every level you beat grants points that can be redeemed for BTC. You’ll need to log in with a Bling account, then exchange points for Bitcoin once you hit the minimum threshold (withdrawals are processed through Coinbase or PayPal similar to Blast)​. Originally, early players enjoyed higher point rewards, but the app has since balanced its economy as the user base grew – so expect to grind through many levels for small payouts.

    Earning Potential: Much like Bitcoin Blast, patience is required. The app notes it takes a long time to collect enough points for any substantial crypto. Don’t expect more than a few satoshis per level; dedicated players report that even hours of play might only net a few cents worth of BTC​. The real value is in the enjoyable bubble-popping gameplay with a Bitcoin theme, giving you a taste of BTC rewards for your arcade skills. It’s a fun time-killer that lets you earn Bitcoin in the tiniest of drips.

    3. Bitcoin Alien Run – Classic Platformer with BTC Prizes

    Overview: Bitcoin Alien Run is a 2D retro platformer by Bitcoin Aliens (a longtime Bitcoin app developer). You control Daniel D’Alien through pixelated levels filled with obstacles and enemies. What sets Alien Run apart is that completing certain levels (and daily missions) can win you actual Bitcoin payouts​wundertrading.com. It’s available on Android (and as a web game), appealing to those who enjoy old-school side-scrollers with a crypto incentive.

    How You Earn Bitcoin: The game features daily challenges and special levels that, once beaten, reward a chunk of satoshis. You’ll need to clear a set number of levels (often 5 in a row for a daily mission) to qualify for a BTC reward. The Bitcoin is paid out directly to your linked wallet or an in-app balance when you succeed. With Alien Run, there’s no point system conversion – you’re directly earning small BTC amounts for hitting gameplay milestones​.

    Earning Potential: Alien Run’s payouts are infrequent but larger per win than the ad-based puzzle games. Skilled players “can earn more than 0.0002 BTC” (20,000 sats) from the toughest missions​. However, reaching those rewards is challenging – levels get finger-breakingly hard, and many players struggle to beat the required stages​. The game has proven it pays (with thousands of players receiving BTC over the years)​, but expect a steep difficulty curve. Overall, it’s a fun, legit way to earn Bitcoin if you love retro platformers and don’t mind a serious challenge.

    4. RollerCoin – Virtual Mining Simulator & Mini-Game Platform

    Overview: RollerCoin turns crypto mining into a game. It’s an online PC/web game where you manage a virtual data center and play mini-games to boost your mining power. The 8-bit style mini-games (with an ’80s arcade vibe) test your reflexes and puzzle-solving for a few minutes each, simulating the work of mining. Meanwhile, you build your “crypto mining farm” with virtual miners and racks. Unlike other titles here, RollerCoin has a whole economy and community built around it.

    How You Earn Bitcoin: In RollerCoin, your goal is to earn mining power (hash rate) by playing the arcade mini-games or by acquiring virtual mining equipment. Your share of the network’s power determines how much Bitcoin (and other crypto) you mine over time.

    Essentially, the better you play, the more mining power you gain – which leads to more satoshis earned in each block reward distribution​. Bitcoin rewards accumulate in your in-game wallet, and you can withdraw them once you reach the minimum withdrawal amount. The game even hosts regular competitions with BTC prizes for top players​.

    Earning Potential: RollerCoin can yield slightly more Bitcoin over the long run, especially if you consistently play the mini-games and reinvest your earnings into better virtual miners. However, starting from scratch, the free route still earns small fractions of BTC daily. Many players use a strategy of grinding games, completing quests, and referrals to slowly increase their mining power.

    It’s a legitimate platform (over 4.8 million players worldwide)​ to learn about mining and earn crypto without any hardware. Just note that progressing to notable earnings takes time (or optionally, spending money on in-game miners). For those who enjoy tycoon-style progression and competition, RollerCoin offers a unique and engaging way to earn Bitcoin while gaming​.

    5. Lightnite – Bitcoin Battle Royale Shooter

    Overview: Lightnite is a multiplayer battle royale game (in the vein of Fortnite) that integrates Bitcoin rewards into its gameplay. It features a low-poly cartoonish art style and fast-paced combat. Players drop into a map, collect gear, and fight until one survives – all while having the chance to pick up and earn Bitcoin in-game. Lightnite is available on PC, and it’s one of the more ambitious blockchain games focused on Bitcoin via the Lightning Network.

    How You Earn Bitcoin: In Lightnite, practically every action can have a micro Bitcoin reward or penalty. You earn BTC by collecting items (like Easter eggs) or loot boxes during matches, and by shooting opponents – when you score a kill, you might loot some of their Bitcoin​. These sats accumulate in your account as you play.

    The game essentially has a circular economy – you can spend Bitcoin within the game (for skins or upgrades) or choose to withdraw your balance. Thanks to Lightning Network integration, you can cash out instantly to a Lightning wallet once you’ve collected some bounty​. No technical crypto knowledge is required to play; Lightnite handles the BTC seamlessly in the background.

    Earning Potential: Lightnite’s rewards depend on your skill and the in-game events. Skilled players who actively eliminate enemies and scavenge can earn more sats per match (plus occasional special events that unlock bonus Bitcoin or even NFTs​). However, since it’s a competitive shooter, earnings are not guaranteed each round – you have to survive and win battles to claim the prizes.

    Don’t expect huge values; the game distributes small BTC loot to keep it sustainable. It’s more about the thrill of earning Bitcoin for every kill than the amount. If you enjoy shooters, Lightnite offers an exciting way to combine gaming with BTC rewards, and you can withdraw your winnings to your own wallet at any time​.

    6. THNDR Games (e.g. Turbo 84, Bitcoin Bay, Solitaire) – Casual Mobile Games with Bitcoin Prizes

    Overview: THNDR Games is a developer specializing in mobile games that pay Bitcoin rewards. They have several hit titles – Turbo 84 (an endless runner driving game), THNDR Bay (a tropical bubble shooter), Club Bitcoin: Solitaire, Bitcoin Snake, and more. These games are simple, free-to-play and filled with quick levels or rounds.

    The unifying theme: as you play any THNDR game, you collect tickets for a Bitcoin prize draw​. The gameplay itself is familiar (e.g. Turbo 84 feels like an arcade racing avoider, and Solitaire is the classic card game), but the chance of winning BTC keeps players hooked.

    How You Earn Bitcoin: THNDR’s model is a bit like a lottery. Each level you complete or achievement you earn grants you THNDR tickets​. These tickets are entries into a daily Bitcoin raffle. Every day, the app randomly selects winners from the ticket pool and awards real Bitcoin prizes (ranging from a few sats to larger chunks). The more tickets you’ve accumulated by playing, the higher your chances of winning in the daily draw​.

    If you win, the BTC is immediately available to withdraw via Lightning – THNDR supports one-tap cashout to wallets like Wallet of Satoshi, ZEBEDEE, etc., with no withdrawal fees or waiting period​. Essentially, play games, earn tickets, and pray to Lady Luck for a Bitcoin payout.

    Earning Potential: The BTC rewards in THNDR games are small but steady. Most days you might win only a handful of satoshis (if anything at all, since it’s luck-based). THNDR has recorded over 500,000 Bitcoin prizes sent out across its user base​, and some dedicated players have amassed meaningful sats over time.

    The prize draw system means occasional lucky players get a higher payout, whereas typical users accumulate a trickle of BTC. The real draw is that these titles are polished and fun casual games first and foremost​ the Bitcoin reward is a bonus that costs nothing to try for. If you’re going to play mobile games, why not play ones that give you a shot at earning Bitcoin?

    7. Idle Mine (Fumb Games) – Hands-Off Mining, Real BTC

    Overview: Idle Mine is a 2024 release that brings Bitcoin rewards to the popular “idle clicker” genre​. In this mobile game (available on Android and iOS), you manage a gem mining operation. Your little miners dig for gems automatically, and you can tap to speed them up or invest in upgrades. It’s a sequel of sorts to Fumb Games’ earlier hit Bitcoin Miner, with a new theme but the same core idea: very minimal gameplay input, but an eventual Bitcoin payout for your time​.

    How You Earn Bitcoin: Idle Mine is integrated with the ZEBEDEE Lightning wallet system​. As your in-game mining operation progresses, you periodically earn small Bitcoin rewards. The game might give you a satoshi bonus for hitting certain milestones or over time as your “idle” earnings accrue.

    When you’re ready, you can withdraw the accumulated BTC to your ZBD wallet (which can then send to any Bitcoin Lightning wallet or convert to cash). There’s no need to keep the app open constantly – it literally idles and generates rewards slowly in the background, with just occasional taps to upgrade your mines or claim bonuses.

    Earning Potential: True to the idle game nature, the BTC trickles in. “The earnings are tiny – keep your expectations in check,” notes one review​. Playing (or idling) for hours might only yield a few cents worth of Bitcoin. But Idle Mine makes it effortless to stack sats; it’s something you can run while multitasking.

    Over weeks of play, those sats can add up to a few dollars in BTC – not much, but not nothing either. The appeal here is less about skill or intensity and more about casually earning Bitcoin with minimal effort. If you enjoy the progression of idle tycoon games, Idle Mine gives that same satisfaction and throws in real BTC rewards on top, which you can spend or save as you please.

    Conclusion

    Crypto gaming in 2025 isn’t just about altcoins and NFTs – as these examples show, you can dive into blockchain games that pay out BTC rewards directly. From puzzles and arcade racers to battle royales and mining simulators, there’s a Bitcoin game for every taste. Remember, the earnings are humble (pennies per hour in most cases​), but the experience is a fun way to learn about Bitcoin and accumulate a few satoshis.

    Whether you’re clearing rows of candies or clearing out enemy players on the battlefield, these bitcoin games let you earn Bitcoin while doing what you love – gaming. Play for enjoyment first, and treat any BTC you win as a bonus, and you’ll get the best out of these play-to-earn Bitcoin games.


    Source link

    Popular Posts

    My Favorites

    Ethereum Traders Buy the Dip Despite Third-Largest Spot Outflow Since October...

    0
    In brief Ethereum's spot outflows hit $359M Monday, the third-largest since October, signaling dip buying. Historical data shows similar outflows preceded price bounces of 7%...